Managing Auto Creation of Database or Message Broker Resources in the Critter Stack vNext

If you’d prefer to start with more context, skip to the section named “Why is this important?”.

To set up the problem I’m hoping to address in this post, there are several settings across both Marten and Wolverine that need to be configured for the most optimal possible functioning between development, testing, and deployment time — but yet, some of these settings are done different ways today or have to be done independently for both Marten and Wolverine.

Below is a proposed configuration approach for Marten, Wolverine, and future “Critter” tools with the Marten 8 / Wolverine 4 “Critter Stack 2025” wave of releases:

        var builder = Host.CreateApplicationBuilder();
        
        // This would apply to both Marten, Wolverine, and future critters....
        builder.Services.AddJasperFx(x =>
        {
            // This expands in importance to be the master "AutoCreate"
            // over every resource at runtime and not just databases
            // So this would maybe take the place of AutoProvision() in Wolverine world too
            x.Production.AutoCreate = AutoCreate.None;
            x.Production.GeneratedCodeMode = TypeLoadMode.Static;
            x.Production.AssertAllPreGeneratedTypesExist = true;
            
            // Just for completeness sake, but these are the defaults
            x.Development.AutoCreate = AutoCreate.CreateOrUpdate;
            x.Development.GeneratedCodeMode = TypeLoadMode.Dynamic;

            // Unify the Marten/Wolverine/future critter application assembly
            // Default will always be the entry assembly
            x.ApplicationAssembly = typeof(Message1).Assembly;
        });
        
        // keep bootstrapping...

If you’ve used either Marten or Wolverine for production usages, you know that you probably want to turn off the dynamic code generation at production time, and you might choose to also turn off the automatic database migrations for both Marten and Wolverine in production (or not, I’ve been surprised how many folks are happy to just let the tools manage database schemas).

The killer problem for us today, is that the settings above have to be configured independently for both Marten and Wolverine — and as a bad coincidence, I just chatted with someone on Discord who got burned by this as I was starting this post. Grr.

Even worse, the syntactical options for disabling automatic database management for Wolverine’s envelope storage tables is a little different syntax altogether. And then just to make things more fun — and please cut the Critter Stack community and I some slack because all of this evolved over years — the “auto create / migrate / evolve” functionality for like Rabbit MQ queues/exchanges/bindings or Kafka topics is “opt in” instead of “opt out” like the automatic database migrations are with a completely different syntax and naming than either the Marten or Wolverine tables as shown with the AutoProvision() option below:

using var host = await Host.CreateDefaultBuilder()
    .UseWolverine(opts =>
    {
        opts.UseRabbitMq(rabbit => { rabbit.HostName = "localhost"; })
            // I'm declaring an exchange, a queue, and the binding
            // key that we're referencing below.
            // This is NOT MANDATORY, but rather just allows Wolverine to
            // control the Rabbit MQ object lifecycle
            .DeclareExchange("exchange1", ex => { ex.BindQueue("queue1", "key1"); })

            // This will direct Wolverine to create any missing Rabbit MQ exchanges,
            // queues, or binding keys declared in the application at application
            // start up time
            .AutoProvision();

        opts.PublishAllMessages().ToRabbitExchange("exchange1");
    }).StartAsync();

I’m not married to the syntax per se, but my proposal is that:

  • Every possible type of “stateful resource” (database configurations or message brokers or whatever we might introduce in the future) by default follows the AutoCreate settings in one place, which for right now is in the AddJasperFx() method (should this be named something else? ConfigureJasperFx(), ConfigureCritterStack() ????
  • You can override this at either the Marten or Wolverine levels, or within Wolverine, maybe you use the default behavior for the application for all database management, but turn down Azure Service Bus to AutoCreate.None.
  • We’ll use the AutoCreate enumeration that originated in Marten, but will now move down to a lower level shared library to define the level for each resource
  • All resource types will have a default setting of AutoCreate.CreateOrUpdate, even message brokers. This is to move the tools into more of a “it just works” out of the box developer experience. This will make the usage of AutoProvision() in Wolverine unnecessary unless you want to override the AutoCreate settings
  • We deprecate the OptimizeArtifactWorkflow() mechanisms that never really caught on, and instead let folks just set potentially different settings for “Development” vs “Production” time, and let the tools apply the right settings based on the IHostEnvironment.Environment name so you don’t have to clutter up your code with too many ugly if (builder.Environment.IsDevelopment() ... calls.

Just for some context, the AutoCreate values are below:

public enum AutoCreate
{
    /// <summary>
    ///     Will drop and recreate tables that do not match the Marten configuration or create new ones
    /// </summary>
    All,

    /// <summary>
    ///     Will never destroy existing tables. Attempts to add missing columns or missing tables
    /// </summary>
    CreateOrUpdate,

    /// <summary>
    ///     Will create missing schema objects at runtime, but will not update or remove existing schema objects
    /// </summary>
    CreateOnly,

    /// <summary>
    ///     Do not recreate, destroy, or update schema objects at runtime. Will throw exceptions if
    ///     the schema does not match the Marten configuration
    /// </summary>
    None
}

For longstanding Critter Stack users, we’ll absolutely keep:

  • The existing “stateful resource” model, including the resources command line helper for setting up or tearing down resource dependencies
  • The existing db-* command line tooling
  • The IServiceCollection.AddResourceSetupOnStartup() method for forcing all resources (databases and broker objects) to be correctly built out on application startup
  • The existing Marten and Wolverine settings for configuring the AutoCreate levels, but these will be marked as [Obsolete]
  • The existing Marten and Wolverine settings for configuring the code generation TypeLoadMode, but the default values will come from the AddJasperFx() options and the Marten or Wolverine options will be marked as [Obsolete]

Why is this important?

An important part of building, deploying, and maintaining an enterprise system with server side tooling like the “Critter Stack” (Marten, Wolverine, and their smaller sibling Weasel that factors quite a bit into this blog post) is dealing with creating or migrating database schema objects or message broker resources so that your application can function as expected against its infrastructure dependencies.

As any of you know who have ever walked into the development of an existing enterprise system, it’s often challenging to get your local development environment configured for that system — and that can frequently cause you days and I’ve even seen weeks of delay. What if instead you could simply start fresh with a clean clone of the code repository and be up and running very quickly?

If you pick up Marten for the first time today, spin up a brand new PostgreSQL database where you have full admin rights, and write this code it would happily work without you doing any explicit work to migrate the new PostgreSQL database:

public class Customer
{
    public Guid Id { get; set; }

    // We'll use this later for some "logic" about how incidents
    // can be automatically prioritized
    public Dictionary<IncidentCategory, IncidentPriority> Priorities { get; set; }
        = new();

    public string? Region { get; set; }

    public ContractDuration Duration { get; set; }
}

public record ContractDuration(DateOnly Start, DateOnly End);

public enum IncidentCategory
{
    Software,
    Hardware,
    Network,
    Database
}

public enum IncidentPriority
{
    Critical,
    High,
    Medium,
    Low
}

await using var store = DocumentStore
    .For("Host=localhost;Port=5432;Database=marten_testing;Username=postgres;password=postgres");

var customer = new Customer
{
    Duration = new ContractDuration(new DateOnly(2023, 12, 1), new DateOnly(2024, 12, 1)),
    Region = "West Coast",
    Priorities = new Dictionary<IncidentCategory, IncidentPriority>
    {
        { IncidentCategory.Database, IncidentPriority.High }
    }
};

// IDocumentSession is Marten's unit of work 
await using var session = store.LightweightSession();
session.Store(customer);
await session.SaveChangesAsync();

// Marten assigned an identity for us on Store(), so 
// we'll use that to load another copy of what was 
// just saved
var customer2 = await session.LoadAsync<Customer>(customer.Id);

// Just making a pretty JSON printout
Console.WriteLine(JsonConvert.SerializeObject(customer2, Formatting.Indented));

Instead, with its default settings, Marten is able to quietly check if its underlying database has all the necessary database tables, functions, sequences, and schemas for whatever it needs roughly when it needs it for the first time. The whole point of this functionality is to ensure that a new developer coming into your project for the very first time can quickly clone your repository, and be up and running either the whole system or even just integration tests that hit the database immediately because Marten is able to “auto-migrate” database changes for you so you can just focus on getting work done.

Great, right? Except that sometimes you certainly wouldn’t want this “auto-migration” business going. Maybe because the system doesn’t have permissions, or maybe just to make the system spin up faster without the overhead of calculating the necessity of a migration step (it’s not cheap, especially for something like a Serverless usage where you depend on fast cold starts). Either way, you’d like to be able to turn that off at production time with the assumption that you’re applying database changes beforehand (which the Critter Stack has worlds of tools to help with as well), so you’ll turn off the default behavior something like the following with Marten 7 and before:

var builder = WebApplication.CreateBuilder(args);

builder.Services.AddMarten(opts =>
    {
        // Other configuration...

        // In production, let's turn off all the automatic database
        // migration stuff
        if (builder.Environment.IsProduction())
        {
            opts.AutoCreateSchemaObjects = AutoCreate.None;
        }
    })
    // Add background projection processing
    .AddAsyncDaemon(DaemonMode.HotCold)
    // This is a mild optimization
    .UseLightweightSessions();

Wolverine uses the same underlying Weasel helper library to make automatic database migrations that Marten does, and works similarly, but disabling the automatic database setup is different for reasons I don’t remember:

using var host = await Host.CreateDefaultBuilder()
    .UseWolverine(opts =>
    {
        // Disable automatic database migrations for message
        // storage
        opts.AutoBuildMessageStorageOnStartup = false;
    }).StartAsync();

Wolverine can do similar automatic management of Rabbit MQ, Azure Service Bus, AWS SQS, Kafka, Pulsar, or Google Pubsub objects at runtime, but in this case you have to explicitly “opt in” to that automatic management through the fluent interface registration of a message broker like this sample using Google Pubsub:

        var host = await Host.CreateDefaultBuilder()
            .UseWolverine(opts =>
            {
                opts.UsePubsub("your-project-id")

                    // Let Wolverine create missing topics and subscriptions as necessary
                    .AutoProvision()

                    // Optionally purge all subscriptions on application startup.
                    // Warning though, this is potentially slow
                    .AutoPurgeOnStartup();
            }).StartAsync();

Wolverine Meets AWS SNS

Wolverine 3.13 added a new message transport for Amazon SNS with a big pull request from Luis Villalaz.

To get started, add this Nuget to your system:

dotnet add package WolverineFx.AmazonSns

Assuming that you have set up a shared AWS configuration or credential files, you can connect to SNS from Wolverine with this:

var host = await Host.CreateDefaultBuilder()
    .UseWolverine(opts =>
    {
        // This does depend on the server having an AWS credentials file
        // See https://docs.aws.amazon.com/cli/latest/userguide/cli-configure-files.html for more information
        opts.UseAmazonSnsTransport()

            // Let Wolverine create missing topics and subscriptions as necessary
            .AutoProvision();
    }).StartAsync();

To set up message publishing with Wolverine, you can use all the standard Wolverine message routing configuration, but use the new ToSnsTopic() extension method like so:

var host = await Host.CreateDefaultBuilder()
    .UseWolverine(opts =>
    {
        opts.UseAmazonSnsTransport();

        opts.PublishMessage<Message1>()
            .ToSnsTopic("outbound1")

            // Increase the outgoing message throughput, but at the cost
            // of strict ordering
            .MessageBatchMaxDegreeOfParallelism(Environment.ProcessorCount)
            .ConfigureTopicCreation(conf =>
            {
                // Configure topic creation request...
            });
    }).StartAsync();
You can also configure subscriptions to SNS topics to Amazon SQS queues like this:

var host = await Host.CreateDefaultBuilder()
    .UseWolverine(opts =>
    {
        opts.UseAmazonSnsTransport()
            // Without this, the SubscribeSqsQueue() call does nothing
            .AutoProvision();

        opts.PublishMessage<Message1>()
            .ToSnsTopic("outbound1")
            // Sets a subscriptions to be
            .SubscribeSqsQueue("queueName",
                config =>
                {
                    // Configure subscription attributes
                    config.RawMessageDelivery = true;
                });
    }).StartAsync();

Summary

Right now Wolverine has support for publishing through Amazon SNS to Amazon SQS queues. I of course do expect additional use cases and further interoperability stories for this transport, but honestly, I just want to react to what folks have a demonstrated need for rather than building anything early. If you have a use case for Amazon SNS with Wolverine that isn’t already covered, please just engage with our community either on Wolverine’s GitHub repository or in our Discord room.

With Wolverine 3.13, our list of supported message brokers has grown to:

  • Rabbit MQ — admittedly our most feature rich and mature transport simply due to how often it’s used
  • Azure Service Bus
  • Amazon SQS
  • Google PubSub — also done through community pull requests
  • Sql Server or PostgreSQL if you just don’t have a lot of messages, but don’t want to introduce new messaging infrastructure. You can also import messages from external database tables as a way to do durable messaging from legacy systems to Wolverine.
  • MQTT for IoT usage
  • Kafka — which has also been improved through recent community feedback and pull requests
  • Apache Pulsar — same as Kafka, there’s suddenly been more community usage and contribution for this transport

I don’t know when and if there will be additional transports, but there are occasional requests for NATS.io or Redis. I think there’s some possibility of a SignalR transport coming out of JasperFx’s internal work on our forthcoming “CritterWatch” tool.

Huge Wolverine 3.13 Release

Wolverine is part of the larger “Critter Stack” suite that provides a robust and productive approach to Event Driven Architecture approaches in the .NET ecosystem. Through its various elements provides an asynchronous messaging framework, an alternative HTTP endpoint framework, and yes, it can be used as just a “mediator” tool (but I’d recommend using Wolverine’s HTTP support directly instead of “Wolverine as MediatR”). What’s special about Wolverine is how much, much more it does to reduce project boilerplate, code ceremony, and the complexity of application code compared to other .NET messaging or “mediator” tools. We the Wolverine team and community would ask that you keep this in mind instead of strictly comparing Wolverine as an apples to apples analogue to other .NET frameworks.

The Wolverine community has been busy, and I was just able to publish a very large Wolverine 3.13 release this evening. I’m happily going to use this release as a demonstration of the health of Wolverine as an ongoing OSS project because it has:

  • Big new features from other core team members like Jakob Tikjøb Andersen‘s work with HTTP form posts and [AsParameters] support
  • A significant improvement in the documentation structure from core team member JT
  • Huge new features from the community like Luis Villalaz‘s addition of an AWS SNS transport for Wolverine
  • An F# usability improvement from the Critter Stack’s de facto F# support owner nkosi23
  • New feature work sponsored by a JasperFx Software client for some specific needs, and this is important for the health of Wolverine because JasperFx support and consulting clients are directly responsible for making Wolverine and the rest of the Critter Stack be viable as a longer term technical choice
  • Quite a few improvements to the Kafka transport that were suggestions from newer community members who came to Wolverine in the aftermath of other tool’s commercialization plans
  • Pull requests that made improvements or fixed problems in the documentation website — and those kinds of little pull requests do make a difference and are definitely appreciated by myself and the other team members
  • New contributors, including Bjørn Madsen‘s improvements to the Pulsar support

Anyway, I’ll be blogging about some of the highlights of this new release starting tomorrow with our new HTTP endpoint capabilities that add some frequently requested features, but I wanted to get the announcement and some thanks out to the community first. And of course, if there’s any issues with the new release or old bits (and there will be), just ask away in the Critter Stack Discord server.

Wrapping Up

Large OSS project releases can sometimes become their own gravity source that sucks in more and more work when a project owner starts getting enamored of doing a big, flashy release. I’d strongly prefer to be a little more steady with weekly or bi-weekly releases instead of ever doing a big release like this, but a lot of things just happened to come in all at once here.

JasperFx Software has some contractural obligations to deliver Wolverine 4.0 soon, so this might be the last big release of new features in the 3.* line.

Preview of (Hopefully) Improved Projections in Marten 8

Work is continuing on the “Critter Stack 2025” round of releases, but we have finally got an alpha release of Marten 8 (8.0.0-alpha-5) that’s good enough for friendly users and core team members to try out for feedback. 8.0 won’t be a huge release, but we’re making some substantial changes to the projections subsystem and this is where I’d personally love any and all feedback about the changes so far that I’m going to try to preview in this post.

Just know that first, here are the goals of the projection changes for Marten 8.0:

  1. Eliminate the code generation for projections altogether and instead using dynamic Lambda compilation with FastExpressionCompiler for the remaining convention-based projection approaches. That’s complete in this alpha release.
  2. Expand the support for strong typed identifiers (Vogen or StronglyTypedId or otherwise) across the public API of Marten. I’m personally sick to death of this issue and don’t particularly believe in the value of these infernal things, but the user community has spoken loudly. Some of the breaking API changes in this post were caused by expanding the strong typed identifier support.
  3. Better support explicit code options for all projection categories (single stream projections, multi-stream projections, flat table projections, or event projections)
  4. Extract the basic event sourcing types, abstractions, and most of the projection and event subscription support to a new shared JasperFx.Events library that is planned to be reusable between Marten and future “Critter” tools targeting Sql Server first, then maybe CosmosDb or DynamoDb. We’ll write a better migration guide later, but expect some types you may be using today to have moved namespaces. I was concerned before starting this work for the 2nd time that it would be a time consuming boondoggle that might not be worth the effort. After having largely completed this planned work I am still concerned that this was a time consuming boondoggle and opportunity cost. Alas.
  5. Some significant performance and scalability improvements for asynchronous projections and projection rebuilds that are still a work in progress

Alright, on to the changes.

Single Stream Projection

Probably the most common projection type is to aggregate a single event stream into a view of that stream as either a “write model” to support decision making in commands or a “read model” to support queries or user interfaces. In Marten 8, you will still use the SingleStreamProjection base class (CustomProjection is marked as obsolete in V8), but there’s one significant change that now you have to use a second generic type argument for the identity type of the projected document (blame the proliferation of strong typed identifiers for this), with this as an example:

// This example is using the old Apply/Create/ShouldDelete conventions
public class ItemProjection: SingleStreamProjection<Item, Guid>
{
    public void Apply(Item item, ItemStarted started)
    {
        item.Started = true;
        item.Description = started.Description;
    }

    public void Apply(Item item, IEvent<ItemWorked> worked)
    {
        // Nothing, I know, this is weird
    }

    public void Apply(Item item, ItemFinished finished)
    {
        item.Completed = true;
    }

    public override Item ApplyMetadata(Item aggregate, IEvent lastEvent)
    {
        // Apply the last timestamp
        aggregate.LastModified = lastEvent.Timestamp;

        var person = lastEvent.GetHeader("last-modified-by");

        aggregate.LastModifiedBy = person?.ToString() ?? "System";

        return aggregate;
    }
}

The same Apply, Create, and ShouldDelete conventions from Marten 4-7 are still supported. You can also still just put those conventional methods directly on the aggregate type just like you could in Marten 4-7.

The inline lambda options are also still supported with the same method signatures:

    public class TripProjection: SingleStreamProjection<Trip, Guid>
    {
        public TripProjection()
        {
            ProjectEvent<Arrival>((trip, e) => trip.State = e.State);
            ProjectEvent<Travel>((trip, e) => trip.Traveled += e.TotalDistance());
            ProjectEvent<TripEnded>((trip, e) =>
            {
                trip.Active = false;
                trip.EndedOn = e.Day;
            });

            ProjectEventAsync<Breakdown>(async (session, trip, e) =>
            {
                var repairShop = await session.Query<RepairShop>()
                    .Where(x => x.State == trip.State)
                    .FirstOrDefaultAsync();

                trip.RepairShopId = repairShop?.Id;
            });
        }
    }

So far the only different from Marten 4-7 is the additional type argument for the identity. Now let’s get into the new options for explicit code when either you just prefer that way, or your logic is too complex for the limited conventional approach.

First, let’s say that you want to use explicit code to “evolve” the state of an aggregated projection, but you won’t need any additional data lookups except for the event data. In this case, you can override the Evolve method as shown below:

public class WeirdCustomAggregation: SingleStreamProjection<MyAggregate, Guid>
{
    public WeirdCustomAggregation()
    {
        ProjectionName = "Weird";
    }

    public override MyAggregate Evolve(MyAggregate snapshot, Guid id, IEvent e)
    {
        // Given the current snapshot and an event, "evolve" the aggregate
        // to the next version.
        
        // And snapshot can be null, just meaning it hasn't been
        // started yet, so start it here
        snapshot ??= new MyAggregate(){ Id = id };
        switch (e.Data)
        {
            case AEvent:
                snapshot.ACount++;
                break;
            case BEvent:
                snapshot.BCount++;
                break;
            case CEvent:
                snapshot.CCount++;
                break;
            case DEvent:
                snapshot.DCount++;
                break;
        }

        return snapshot;
    }
}

I should note that you may want to explicitly configure what event types the projection is interested in as a way to optimize the projection when running in the async daemon.

Now, if you want to “evolve” a snapshot with explicit code, but you might need to do query some reference data as you do that, you can instead override the asynchronous EvolveAsync method with this signature:

    public virtual ValueTask<TDoc?> EvolveAsync(TDoc? snapshot, TId id, TQuerySession session, IEvent e,
        CancellationToken cancellation)

But wait, there’s (unfortunately) more options! In the recipes above, you’re assuming that the single stream projection has a simplistic lifecycle of being created, updated one or more times, then maybe being deleted and/or archived. But what if you have some kind of complex workflow where the projected document for a single event stream might be repeatedly created, deleted, then restarted? We had to originally introduce the CustomProjection mechanism to Marten 6/7 as a way of accommodating complex workflows, especially when they involved soft deletes of the projected documents. In Marten 8, we’re (for now) proposing reentrant workflows with this syntax by overriding the DetermineAction() method like so:

public class StartAndStopProjection: SingleStreamProjection<StartAndStopAggregate, Guid>
{
    public StartAndStopProjection()
    {
        // This is an optional, but potentially important optimization
        // for the async daemon so that it sets up an allow list
        // of the event types that will be run through this projection
        IncludeType<Start>();
        IncludeType<End>();
        IncludeType<Restart>();
        IncludeType<Increment>();
    }

    public override (StartAndStopAggregate?, ActionType) DetermineAction(StartAndStopAggregate? snapshot, Guid identity,
        IReadOnlyList<IEvent> events)
    {
        var actionType = ActionType.Store;

        if (snapshot == null && events.HasNoEventsOfType<Start>())
        {
            return (snapshot, ActionType.Nothing);
        }

        var eventData = events.ToQueueOfEventData();
        while (eventData.Any())
        {
            var data = eventData.Dequeue();
            switch (data)
            {
                case Start:
                    snapshot = new StartAndStopAggregate
                    {
                        // Have to assign the identity ourselves
                        Id = identity
                    };
                    break;

                case Increment when snapshot is { Deleted: false }:

                    if (actionType == ActionType.StoreThenSoftDelete) continue;

                    // Use explicit code to only apply this event
                    // if the snapshot already exists
                    snapshot.Increment();
                    break;

                case End when snapshot is { Deleted: false }:
                    // This will be a "soft delete" because the snapshot type
                    // implements the IDeleted interface
                    snapshot.Deleted = true;
                    actionType = ActionType.StoreThenSoftDelete;
                    break;

                case Restart when snapshot == null || snapshot.Deleted:
                    // Got to "undo" the soft delete status
                    actionType = ActionType.UnDeleteAndStore;
                    snapshot.Deleted = false;
                    break;
            }
        }

        return (snapshot, actionType);
    }

}

And of course, since *some* of you will do even more complex things that will require making database calls through Marten or maybe even calling into external web services, there’s an asynchronous alternative as well with this signature:

    public virtual ValueTask<(TDoc?, ActionType)> DetermineActionAsync(TQuerySession session,
        TDoc? snapshot,
        TId identity,
        IIdentitySetter<TDoc, TId> identitySetter,
        IReadOnlyList<IEvent> events,
        CancellationToken cancellation)

Multi-Stream Projections

Multi-stream projections are similar in mechanism to single stream projections, but there’s an extra step of “slicing” or grouping events across event streams into related aggregate documents. Experienced Marten users will be aware that the “slicing” API in Marten has not been the most usable API in the world. I think that even though it didn’t change *that* much in Marten 8, the “slicing” will still be easier to use.

First, here’s a sample multi-stream projection that didn’t change at all from Marten 7:

public class DayProjection: MultiStreamProjection<Day, int>
{
    public DayProjection()
    {
        // Tell the projection how to group the events
        // by Day document
        Identity<IDayEvent>(x => x.Day);

        // This just lets the projection work independently
        // on each Movement child of the Travel event
        // as if it were its own event
        FanOut<Travel, Movement>(x => x.Movements);

        // You can also access Event data
        FanOut<Travel, Stop>(x => x.Data.Stops);

        ProjectionName = "Day";

        // Opt into 2nd level caching of up to 100
        // most recently encountered aggregates as a
        // performance optimization
        Options.CacheLimitPerTenant = 1000;

        // With large event stores of relatively small
        // event objects, moving this number up from the
        // default can greatly improve throughput and especially
        // improve projection rebuild times
        Options.BatchSize = 5000;
    }

    public void Apply(Day day, TripStarted e)
    {
        day.Started++;
    }

    public void Apply(Day day, TripEnded e)
    {
        day.Ended++;
    }

    public void Apply(Day day, Movement e)
    {
        switch (e.Direction)
        {
            case Direction.East:
                day.East += e.Distance;
                break;
            case Direction.North:
                day.North += e.Distance;
                break;
            case Direction.South:
                day.South += e.Distance;
                break;
            case Direction.West:
                day.West += e.Distance;
                break;

            default:
                throw new ArgumentOutOfRangeException();
        }
    }

    public void Apply(Day day, Stop e)
    {
        day.Stops++;
    }
}

The options to use conventional Apply/Create methods or to override Evolve, EvolveAsync, DetermineAction, or DetermineActionAsync are identical to SingleStreamProjection.

Now, on to a more complicated “slicing” sample with custom code:

public class UserGroupsAssignmentProjection: MultiStreamProjection<UserGroupsAssignment, Guid>
{
public UserGroupsAssignmentProjection()
{
CustomGrouping((_, events, group) =>
{
group.AddEvents<UserRegistered>(@event => @event.UserId, events);
group.AddEvents<MultipleUsersAssignedToGroup>(@event => @event.UserIds, events);

return Task.CompletedTask;
});
}

I know it’s not that much simpler than Marten 8, but one thing Marten 8 is doing is handling tenancy grouping behind the scenes for you so that you can just focus on defining how events apply to different groupings. The sample above shaves 3-4 lines of code and a level or two of nesting from the Marten 7 equivalent.

EventProjection and FlatTableProjection

The existing EventProjection and FlatTableProjection models are supported in their entirety, but we will have a new explicit code option with this signature:

public virtual ValueTask ApplyAsync(TOperations operations, IEvent e, CancellationToken cancellation)

And of course, you can still just write a custom IProjection class to go straight down to the metal with all your own code, but that’s been simplified a little bit from Marten 7 such that you don’t have to care about whether it’s running Inline or in Async lifetimes:

    public class QuestPatchTestProjection: IProjection
    {
        public Guid Id { get; set; }

        public string Name { get; set; }

        public Task ApplyAsync(IDocumentOperations operations, IReadOnlyList<IEvent> events, CancellationToken cancellation)
        {
            var questEvents = events.Select(s => s.Data);

            foreach (var @event in questEvents)
            {
                if (@event is Quest quest)
                {
                    operations.Store(new QuestPatchTestProjection { Id = quest.Id });
                }
                else if (@event is QuestStarted started)
                {
                    operations.Patch<QuestPatchTestProjection>(started.Id).Set(x => x.Name, "New Name");
                }
            }
            return Task.CompletedTask;
        }
    }

What’s Still to Come?

I’m admittedly cutting this post short just because I’m a good (okay, not horrible) Dad and it’s time to do bedtime in a minute. Beyond just responding to whatever feedback comes in, there’s some more test cases for the explicit coding options, more samples to write for documentation, and a seemingly endless array of use cases for strong typed identifiers.

Beyond that, there’s still a significant effort to come with Marten 8 to try some performance and scalability optimizations for asynchronous projections, but I’ll warn you all that anything too complex is likely to land in our theoretical paid add on model.

A Quick Note About JasperFx’s Plans for Marten & Wolverine

So, yes, Wolverine overlaps quite a bit with both MediatR and MassTransit. If you’re a MediatR user, Wolverine just does a helluva lot more and we have an existing guide for converting from MediatR to Wolverine. For MassTransit (or NServiceBus) users, Wolverine covers a lot of the same asynchronous messaging framework use cases, but does much, much more to simplify your application code than any other .NET messaging framework and should not be compared as an apples to apples messaging feature comparison. And no other tool in the entire .NET ecosystem can come even remotely close to the Critter Stack’s support for Event Sourcing from soup to nuts.

It’s kind of a big day in .NET OSS news with both MediatR and MassTransit respectively announcing moves to commercial licensing models. I’d like to start by wishing the best of luck to my friends Jimmy Bogard and Chris Patterson respectively with their new ventures.

As any long term participant in or observer of the .NET ecosystem knows, there’s about to be a flood of negativity from various people in our community about these moves. There will also be an outcry from a sizable cohort in the .NET community who seem to believe that all development tools should be provided by Microsoft and that only Microsoft can ever be a reliable supplier of these types of tools while somehow suffering from amnesia about how Microsoft has frequently abandoned high profile tools like Silverlight or WCF.

As for Marten, Wolverine, and other future Critter Stack tools, the current JasperFx Software strategy remains following the “open core” model where the existing capabilities in the MIT-licensed tools (note below) remain under an OSS license and JasperFx Software focuses on services, support plans, and the forthcoming commercial CritterWatch tool for monitoring, management, and some advanced features for data privacy, multi-tenancy, and extreme scalability. While we certainly respect MassTransit’s decision, we’re going to try a different path and stay down the “open core” model and Marten 8 / Wolverine 4 will be released under the MIT OSS license. I will admit that you may see some increasing reluctance to be providing as much free support through Discord as we have to users in the past though.

To be technical, there is one existing feature in Marten 7.* for optimized projection rebuilds that I think we’ll redesign and move to the commercial add on tooling in the Marten 8 timeframe, but in this case the existing feature is barely usable anyway so ¯\_(ツ)_/¯

Critter Stack Work in Progress

It’s just time for an update from my last post on Critter Stack Roadmap Update for February as the work has progressed in the past weeks and we have more clarity on what’s going to change.

Work is heavily underway right now for a round of related releases in the Critter Stack (Marten, Wolverine, and other tools) I was originally calling “Critter Stack 2025” involving these tools:

Ermine for Event Sourcing with SQL Server

“Ermine” is our next full fledged “Critter” that’s been a long planned port of a significant subset of Marten’s functionality to targeting SQL Server. At this point, the general thinking is:

  • Focus on porting the Event Sourcing functionality from Marten
  • Quite possibly build around the JSON field support in EF Core and utilize EF Core under the covers. Maybe.
  • Use a new common JasperFx.Events library that will contain the key abstractions, metadata tracking, and even projection support. This new library will be shared between Marten, Ermine, and theoretical later “critters” targeting CosmosDb or DynamoDb down the line
  • Maybe try to lift out more common database handling code from Marten, but man, there’s more differences between PostgreSQL and SQL Server than I think people understand and that might turn into a time sink
  • Support the same kind of “aggregate handler workflow” integration with Wolverine as we have with Marten today, and probably try to do this with shared code, but that’s just a detail

Is this a good idea to do at all? We’ll see. The work to generalize the Marten projection support has been a time sink so far. I’ve been told by folks for a decade that Marten should have targeted SQL Server, and that supporting SQL Server would open up a lot more users. I think this is a bit of a gamble, but I’m hopeful.

JasperFx Dependency Consolidation

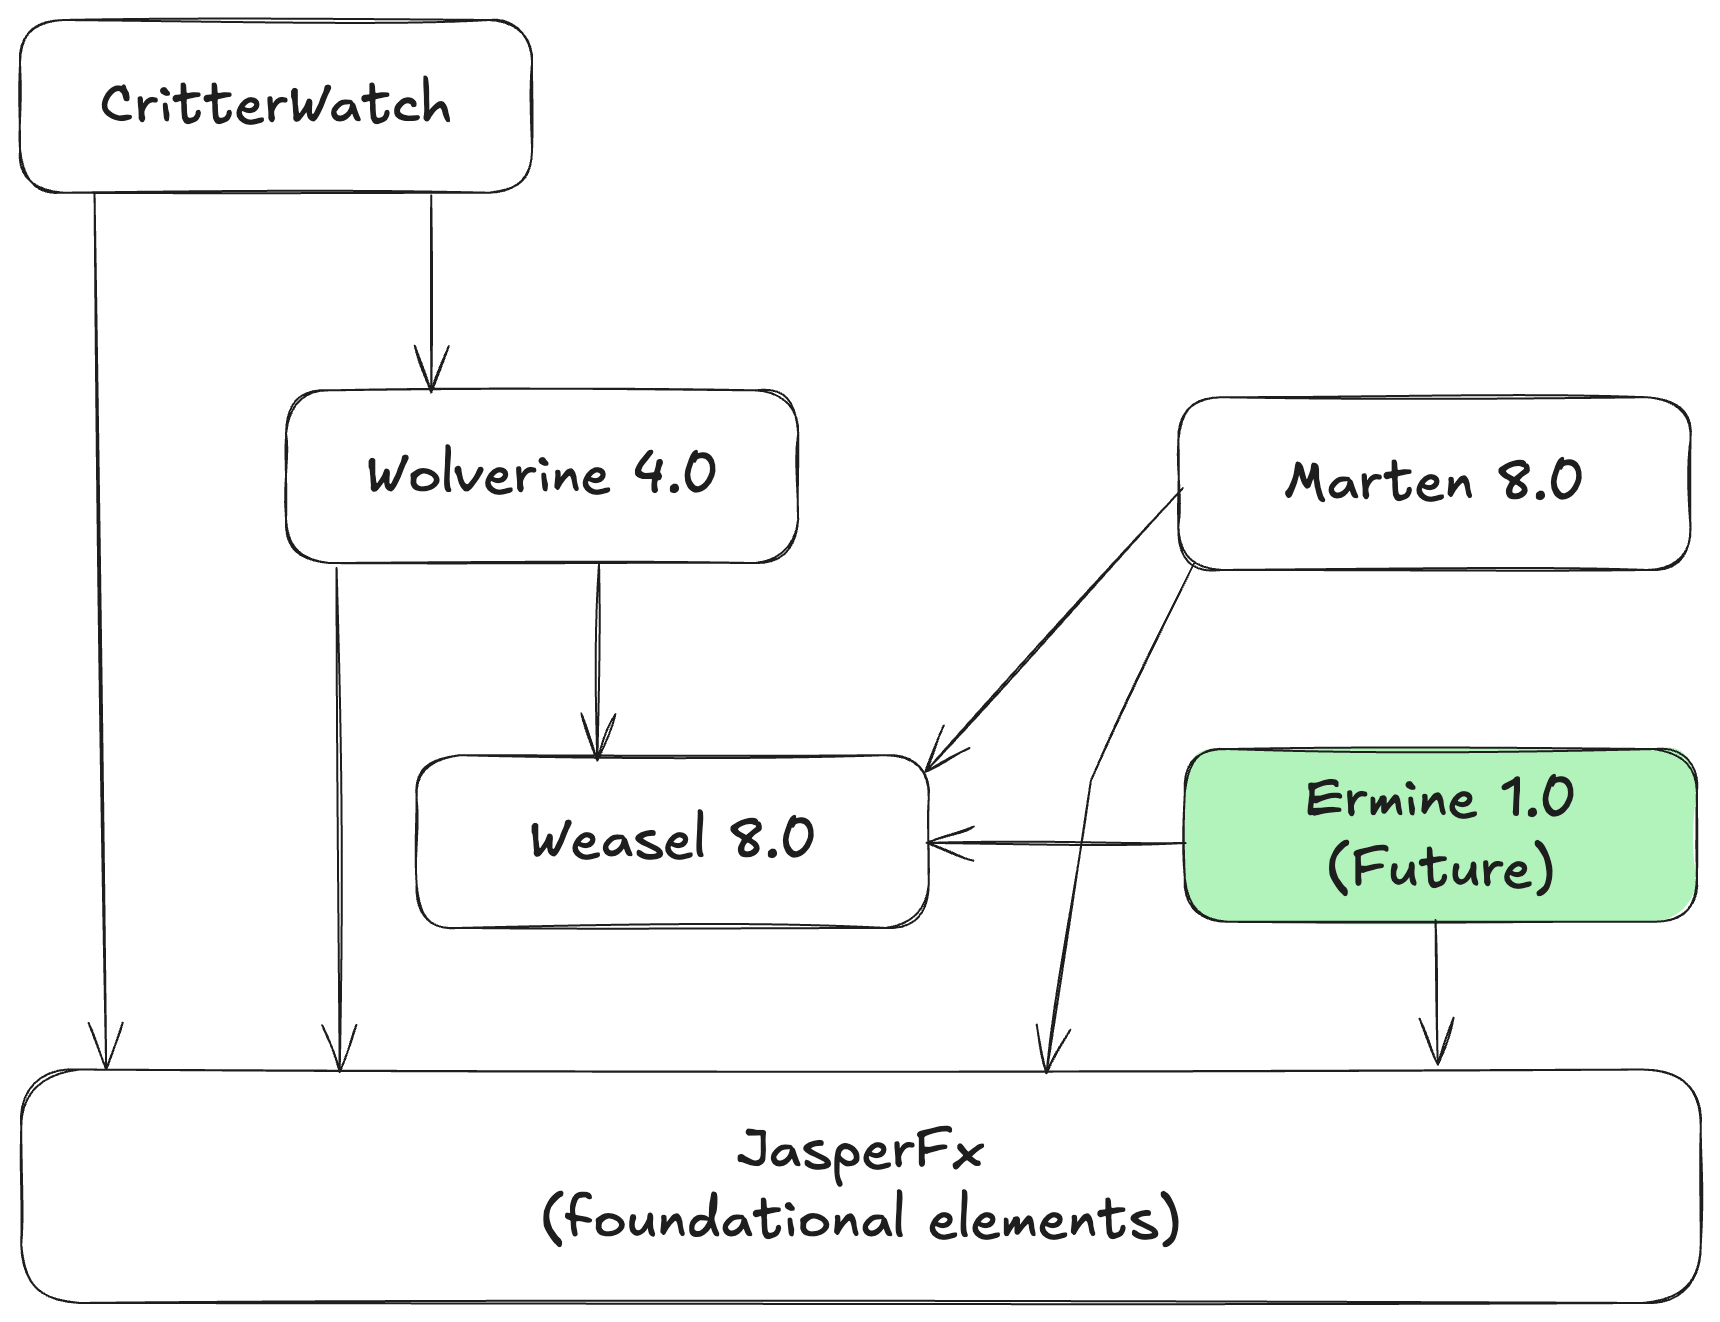
Most of the little, shared foundational elements of Marten, Wolverine, and soon to be Ermine have been consolidated into a single JasperFx library. That now includes what was:

  1. JasperFx.Core (which in turn was renamed from “Baseline” after someone else squatted on that name and in turn was imported from ancient FubuCore for long term followers of mine)
  2. JasperFx.CodeGeneration
  3. The command line discovery, parsing, and execution model that is in Oakton today. That might be a touch annoying for the initial conversion, but in the little bit longer term that’s allowed us to combine several Nuget packages and simplify the project structure over all. TL;DR: fewer Nugets to install going forward.

Marten 8.0

I hope that Marten 8.0 is a much smaller release than Marten 7.0 was last year, but the projection model changes are turning out to be substantial. So far, this work has been done:

  • .NET 6/7 support has been dropped and the dependency tree simplified after that
  • Synchronous database access APIs have been eliminated
  • All other API signatures that were marked as [Obsolete] in the latest versions of Marten 7.* were removed
  • Marten.CommandLine was removed altogether, but the “db-*” commands are available as part of Marten’d dependency tree with no difference in functionality from the “marten-*” commands
  • Upgraded to the latest Npgsql 9

The projection subsystem overhaul is ongoing and substantial and frankly I’m kind of expecting Vizzini to show up in my home office and laugh at me for starting a land war in Southeast Asia. For right now I’ll just say that the key goals are:

  • The aforementioned reuse with Ermine and potential other Event Store implementations later
  • Making it as easy as possible to use explicit code instead as desired for the projections in addition to the existing conventional Apply / Create methods
  • Eliminate code generation for just the projections
  • Simplify the usage of “event slicing” for grouping events in multi-stream projections. I’m happy how this is shaping up so far, and I think this is going to end up being a positive after the initial conversion
  • Improve the throughput of the async daemon

There’s also a planned “stream compacting” feature happening, but it’s too early to talk about that much. Depending on how the projection work goes, there may be other performance related work as well.

Wolverine 4.0

Wolverine 4.0 is mostly about accomodating the work in other products, but there are some changes. Here’s what’s already been done:

  • Dropped .NET 7 support
  • Significant work for a single application being able to use multiple databases from within one application for folks getting clever with modular monoliths. In Wolverine 4.*, you’ll be able to mix and match any number of data stores with the corresponding transactional inbox/outbox support much better than Wolverine 3.* can do. This is 100% about modular monoliths, but also fit into the CritterWatch work
  • Work to provide information to CritterWatch

There are some other important features that might be part of Wolverine 4.0 depending on some ongoing negotiations with a potential JasperFx customer.

CritterWatch Minimal Viable Product Direction

“CritterWatch” is a long planned commercial add on product for Wolverine, Marten, and any future “critter” Event Store tools. The goal is to create both a management and monitoring dashboard for Wolverine messaging and the Event Sourcing processes in those systems.

The initial concept is shown below:

At least for the moment, the goal of the CritterWatch MVP is to deliver a standalone system that can be deployed either in the cloud or on a client premises. The MVP functionality set will:

  • Explain the configuration and capabilities of all your Critter Stack systems, including some visualization of how messages flow between your systems and the state of any event projections or subscriptions
  • Work with your OpenTelemetry tracking to correlate ongoing performance information to the artifacts in your system.
  • Visualize any ongoing event projections or subscriptions by telling you where each is running and how healthy they are — as well as give you the ability to pause, restart, rebuild, or rewind them as needed
  • Manage the dead letter queued (DLQ) messages of your system with the ability to query the messages and selectively replay or discard the DLQ messages

We have a world of other plans for CritterWatch, but the feature set above is the most requested features from the companies that are most interested in this tool first.

Pretty Substantial Wolverine 3.11 Release

The Critter Stack community just made a pretty big Wolverine 3.11 release earlier today with 5 brand new contributors making their first pull requests! The highlights are:

  • Efficiency and throughput improvements for publishing messages through the Kafka transport
  • Hopefully more resiliency in the Kafka transport
  • A fix for object disposal mechanics that probably got messed up in the 3.0 release (oops on my part)
  • Improvements for the Azure Service Bus transport‘s ability to handle larger message batches
  • New options for the Pulsar transport
  • Expanded ability for interop with non-Wolverine services with the Google Pubsub transport
  • Some fixes for Wolverine.HTTP

Wolverine 4.0 is also under way, but there will be at least some Wolverine.HTTP improvements in the 3.* branch before we get to 4.0.

Big thanks to the whole Critter Stack community for continuing to support Wolverine, including the folks who took the time to create actionable bug reports that led to several of the fixes and the folks who made fixes to the documentation website as well!

Nobody Codes a Bad System On Purpose

I have been writing up a little one pager for a JasperFx Software client for their new CTO on why and how their flagship system could use some technical transformation and modernization. I ran my write up past one of their senior developers that I’ve been collaborating on for tactical performance improvements, and he more or less agreed with everything but felt bad that I was maybe throwing the original development team (all since departed for other opportunities) under the bus a bit — my words, not his.

My response was that their planned approach might have been working just fine upfront when the system was simpler, but maybe they would have happily and competently adapted over time as the system overgrew the original patterns and reference architecture, but just weren’t around to get that feedback.

And let’s be honest, I know I’ve created some clever architectures that got dropped on unsuspecting other people in my day too. Including the (actually kind of successful) workflow system I did in Classic ASP + Oracle that had ~70 metadata tables and the system that was written in 6 different programming languages.

That brings me finally to my main point here, and that’s even though I see plenty of systems where the codebase is very challenging to work with and puts the system at risk, I don’t think that any of the teams were necessarily incompetent or didn’t care about doing good work or didn’t have an organized theory about how the code should be structured or even what the architecture should be. Moreover, I can’t say that I’ve even seen a true, classic ball of mud in a couple decades.

Instead, I would say that the systems that I’ve seen in the past decade that were widely known as having code that was hard to work on and suffered from poor performance all had a pretty cohesive coding approach and architecture. The real problem was that at some point the system or the database had grown enough to expose the flaws in the approach or simply grown too complex to be confined within the system’s prescriptive approach, but the teams who owned those systems did not, or were not able to, adapt over time.

To try to make this post not ramble on too long, here’s a couple follow up points:

  • I think that if you have technical ownership over any kind of large system, or are tasked with creating what’s likely going to grow to become a large system, you should adopt an attitude of constantly challenging the basic approach and at a minimum, being aware of when intended changes to the system are difficult because of the current architectural approach
  • Moderate on the idea of consistency throughout your codebase or at least between features. On my recent appearance on DotNetRocks, I veered into a sports metaphor about “raising the floor” vs “raising the ceiling” of the technical quality of a codebase. Technical leads who are worried about consistency and prescriptive project templates are trying to “raise the floor” on code quality — and that works to a point. On the other hand, I think that if you empower a development team to adapt or change their technical approach over time or even just for new subsystems, and if the team has the skillset to do so, you can “raise the ceiling” on technical quality because I have found that one of the main contributors to bad system code is rigid adherence to some kind of prescriptive approach that just doesn’t scale up to the more complicated use cases in a big system.
  • If you follow me or have ever stumbled into many discussions about the Critter Stack, you’ll know that I very strongly believe that reducing code ceremony. For me this means forsaking too many abstractions over persistence, reducing layering, favoring a vertical slice architecture, and honestly, letting in some “magic” through conventional approaches (that’s a debate all by itself of course). I think there’s a huge advantage in being able to easily reason about a codebase throughout a use case from system inputs all the way down to the database. On the other side of that, I think that complex layering strategies will often put too many layers of code to the point where teams cannot easily understand the cause and effect between system inputs and what the outcomes actually are. That is, I think, the number one cause of poor system performance by teams comes from not being able to easily see how chatty a system becomes between its front end, server layer, and database. As an aside, I’ve seen OpenTelemetry tracing be a godsend for identifying performance bottlenecks in unnecessarily complicated code by showing you exactly how many queries a single web request is really making.
  • Just to hammer on the code ceremony angle yet again, I think the only truly reliable way to arrive at a good system that meets your company’s needs over time and is easy to change is iteration and adaptation. High ceremony coding approaches retard your ability to quickly iterate and adapt, and but more of an onus on teams to get things right upfront — which just isn’t consistently possible no matter how hard your try.

Summary

Anyway, to close out, I think that the mass majority of us really do care about doing a good job in our software development work, but we’re all quite capable of having ideas about how a system should be coded, structured, and architected that simply will not work out over time. The only real solution is empowered teams that constantly adapt as necessary instead of letting a codebase get out of control in the first place.

Wait, what’s that you ask? How do you work with your product owners to give you the space to do that? And that’s my cue to start my week long vacation!

Good luck folks, and try to be a little easier on your feelings toward the “previous folks”. And that goes double for me.

And look, I got through this whole post without ranting about how prescriptive Onion/Clean/Hexagonal/Ports and Adapters/iDesign approaches and all the cruft that the DDD community dares each other to build into systems is the root of all coding evil! Oops, never mind.

New Critter Stack Features

JasperFx Software offers custom consulting engagements or ongoing support contracts for any part of the Critter Stack. Some of the features in this post were either directly part of client engagements or inspired by our work with JasperFx clients.

This week brought out some new functionality and inevitably some new bug fixes in Marten 7.38 and Wolverine 3.10. I’m actually hopeful this is about the last Marten 7.* release, and Marten 8.0 is heavily underway. Likewise, Wolverine 3.* is probably about played out, and Wolverine 4.0 will come out at the same time. For now though, here’s some highlights of new functionality.

Delete All Marten Data for a Single Tenant

A JasperFx client has a need to occasionally remove all data for a single named tenant across their entire system. Some of their Marten documents and the events themselves are multi-tenanted, while others are global documents. In their particular case, they’re using Marten’s support for managed table partitions by tenant, but other folks might not. To make the process of cleaning out all data for a single tenant as easy as possible regardless of your particular Marten storage configuration, Marten 7.38 added this API:

public static async Task delete_all_tenant_data(IDocumentStore store, CancellationToken token)
{
    await store.Advanced.DeleteAllTenantDataAsync("AAA", token);
}

Rabbit MQ Quorum Queues or Streams with Wolverine

At the request of another JasperFx Software customer, Wolverine has the ability to declare Rabbit MQ quorum queues or streams like so:

var builder = Host.CreateApplicationBuilder();
builder.UseWolverine(opts =>
{
    opts
        .UseRabbitMq(builder.Configuration.GetConnectionString("rabbit"))
        
        // You can configure the queue type for declaration with this
        // usage as well
        .DeclareQueue("stream", q => q.QueueType = QueueType.stream)

        // Use quorum queues by default as a policy
        .UseQuorumQueues()

        // Or instead use streams
        .UseStreamsAsQueues();

    opts.ListenToRabbitQueue("quorum1")
        // Override the queue type in declarations for a
        // single queue, and the explicit configuration will win
        // out over any policy or convention
        .QueueType(QueueType.quorum);
   
    
});

Note that nothing in Wolverine changed other than giving you the ability to make Wolverine declare Rabbit MQ queues as quorum queues or as streams.

Easy Access to Marten Event Sourced Aggregation Data in Wolverine

While the Wolverine + Marten “aggregate handler workflow” is a popular feature for command handlers that may need to append events, sometimes you just want a read only version of an event sourced aggregate. Marten has its FetchLatest API that lets you retrieve the current state of an aggregated projection consistent with the current event store data regardless of the lifecycle of the projection (live, inline, or async). Wolverine now has a quick short cut for accessing that data as a value “pushed” into your HTTP endpoints by decorating a parameter of your handler method with the new [ReadAggregate] attribute like so:

[WolverineGet("/orders/latest/{id}")]
public static Order GetLatest(Guid id, [ReadAggregate] Order order) => order;

or injected into a message handler similarly like this:

public record FindAggregate(Guid Id);

public static class FindLettersHandler
{
    // This is admittedly just some weak sauce testing support code
    public static LetterAggregateEnvelope Handle(
        FindAggregate command, 
        [ReadAggregate] LetterAggregate aggregate)
    
        => new LetterAggregateEnvelope(aggregate);
}

This feature was inspired by a session with a JasperFx Software client where their HTTP endpoints frequently needed to access projected aggregate data for multiple event streams, but only append events to one stream. This functionality was probably already overdue anyway as a way to quickly get projection data any time you just need to read that data as part of a command or query handler.

We Don’t Need No Stinkin’ Repositories and Other Observations on DotNetRocks

I had a conversation with the DotNetRocks fellows a little while back that posted today, ostensibly about the “Vertical Slice Architecture” approach. We hit several topics along the way mostly related on my — and the Critter Stack’s — philosophy of low code ceremony and reduced layering as the preferred way to succeed in longer term software systems.

So roughly, here’s what I said or at least tried to say:

I would generally recommend against using wrapping repository abstractions around low level persistence tooling like Marten, EF Core, or Dapper in systems in most cases. Hence the title of this post:). I say this for a couple reasons:

  1. The typical IRepository<T> abstraction does pretty well nothing to add any value and frequently blows up the complexity of code when you inevitably have use cases that work on more than one domain entity type at a time
  2. Those abstractions frequently push teams toward using least common denominator capabilities of those tools and accidentally eliminate the usage of a lot of features like batch data querying that would help make system performance better
  3. Despite the theory that using these abstractions will make it easier or at least possible to swap out technical infrastructure later, I think that’s patently not true, especially not when these abstractions are combined with an emphasis on horizontal layering by technical concern and every little bit of data access for the system is in one giant project.

Instead, I prefer to directly utilize Marten or RavenDb’s IDocumentSession or an EF Core DbContext and utilize every last bit of special capabilities these tools have to improve performance. Moreover, following that theme of “vertical slice”, if some kind of database query is only used by a single HTTP request or command handler, I’d strongly prefer that query be right smack dab in the vertical slice code instead of scattered all over your codebase in different horizontal layers because that frequently has some bearing on understanding how the entire message handling or HTTP request or whatever the transaction is actually works.

A large part of this is the feeling that we mostly need to reason about the complete functionality of a single use case or a closely related set of use cases at a time from system inputs down to database queries. On the other hand, I have almost never needed to reason about a system’s entire data access layer in isolation even though that’s held up as an advantage of Clean/Onion/Hexagonal layering approaches. Some folks will argue that there’s value in having all the system’s business logic in one domain layer, but I would think that’s not that valuable in a bigger system anyway.

I think a reasonable person could easily disagree with everything I just said with concerns about testability, consistency in code (a little bit overrated in my personal opinion), and the coupling to technical infrastructure. On that note, let’s shift to what I think does actually lead to maintainable system code:

Code that is easy to reason about. At this point, I think this is the single most important attribute of a long lived, non trivial sized business system that is constantly needing to change. The harder it is for the developers working on the system to understand the impact of changes in logic are within the system, or the harder it is to understand the behavior of the code around a reported bug, the less successful you’ll be. In my experience, the very techniques that we’ve been told lead to maintainable code (layering, abstractions, dependency inversion, prescriptive architectural patterns) are a large part of why systems I’ve worked with have been hard to reason about. To that end, I’m a big believer in reducing code ceremony and code noise so it’s easier to read (and write) the code by just having less junk to wade through. I also strongly recommend trying collapse layering so that it’s easier to just see how an entire feature actually works by having a lot less code to wade through and putting the closely related code together regardless of its technical stereotype (the very basis of the whole “vertical slice” idea).

Effective automated testing coverage. The single best way to truly have “reversible” technical decisions or just being able to actually upgrade technical infrastructure is having a strong level of automated test coverage to make changing the system safe.

With this emphasis on effective test coverage, I naturally believe in having testable code as an important enabler — but yet I’m strongly recommending reducing the number of abstractions and layering that many feel is necessary for testability. To that end, Wolverine’s encourages the idea of the A Frame Architecture approach to “vertical slices” as a way to achieve high testability without having to introduce abstractions and bloat your IoC container. Plus it’s just nice being able to write focused unit tests on business logic without having to fuss with lots of testing fakes. To be clear, I absolutely think it is possible to keep your business logic decoupled from infrastructure concerns without having to introduce additional layers of abstraction and layering.

Organize code around the “verbs” of the system more than the “nouns” (entities) of the system. Especially for a system that has any level of workflow logic rather than being a straight up CRUD system (and if you’re truly building a CRUD system, I think you can ignore everything I’ve said and just go bang out code). So structure your code around an “approve invoice” handler, and not automatically by the “Invoice” entity. And especially don’t prematurely try to divide up a system into separate micro-services or bounded contexts by entity. That’s maybe another way of saying “vertical slice”, but the point here is to avoid having massively bloated “InvoiceController” or “InvoiceRepository” classes that take part in a potentially large number of use cases. When you are dividing your system into separate modules or bounded contexts, pay attention to where the messages are going in between. If you ever have 2 or more modules that frequently have to access each other’s data or change together or be chatty in terms of messaging between themselves, you’re probably wanting to combine them into one single bounded context even if they technically involve more than one entity (invoice *and* inventory in one context maybe). It’s easy to reason about the shape of the system data sometimes, but that noun-centric/data-centric code organization doesn’t lend itself to code that’s easy to reason about when the workflow gets complicated in my experience.

If you possibly can, keep the system somewhat modularized so you could technically upgrade libraries or frameworks or databases in part of the system at a time. You can do all the “Clean Architecture” layering you want, but if your system is huge and there’s just one giant horizontal technical layer for data access, you won’t be able to swap it out easily because of the sheer amount of effort it might take to regression test the entire system when we all know damn well that your product managers will not give you months at a tie with no feature work just to do technical upgrades.

In the absence of reasons not to, I would strongly recommend defaulting to technology choices that play nicely in local integration testing. For a concrete example, if there’s no compelling reason otherwise, I’d prefer to use Rabbit MQ over Azure Service Bus strictly because Rabbit MQ has a fantastic local development story and Azure Service Bus does not (the new emulator is a nice step, but I didn’t find it to be usable yet). Likewise, PostgreSQL with Marten makes it very easy to quickly spin up an application database from a fresh Docker image for fast local development and isolated integration tests.

    There’s a reddit thread going right now about people’s experiences with “vertical slice architecture vs clean architecture” on the /dotnet subreddit, and the one and only one thing that’s clear is that there’s a ton of disagreement about what the hell it is that “vertical slice architecture” actually means and a lot of folks conflating that with bounded contexts or micro-services. My takeaway is that like “ReST” before it, the “vertical slice” nomenclature may be quickly made useless by the variance of understanding of that terminology.

    Summary

    I banged this out fast and it probably shows. I’ll aim for some YouTube videos expanding on this some day soon.