A Vision for Low Ceremony CQRS with Event Sourcing that combined some new functionality in Marten together with Jasper’s execution pipeline and middleware strategy to show how CQRS command handlers can be built with very minimal code ceremony
The message types and Jasper handlers are basically identical to those in my last post if you want a reference. In the Pinger application, I’ve added a reference to the Jasper.RabbitMQ Nuget library, which adds transitive references to Jasper itself and the Rabbit MQ client library. In the application bootstrapping, I’ve got this to connect to Rabbit MQ, send Ping messages to a Rabbit MQ exchange named *pings*, and add a hosted service just to send a new Ping message once a second:
using System.Net.NetworkInformation;
using Jasper;
using Jasper.RabbitMQ;
using Oakton;
using Pinger;

return await Host.CreateDefaultBuilder(args)
    .UseJasper(opts =>
    {
        // Listen for messages coming into the pongs queue
        opts
            .ListenToRabbitQueue("pongs")

            // This won't be necessary by the time Jasper goes 2.0
            // but for now, I've got to help Jasper out a little bit
            .UseForReplies();

        // Publish messages to the pings queue
        opts.PublishMessage<Ping>().ToRabbitExchange("pings");

        // Configure Rabbit MQ connection properties programmatically
        // against a ConnectionFactory
        opts.UseRabbitMq(rabbit =>
        {
            // Using a local installation of Rabbit MQ
            // via a running Docker image
            rabbit.HostName = "localhost";
        })
            // Directs Jasper to build any declared queues, exchanges, or
            // bindings with the Rabbit MQ broker as part of bootstrapping time
            .AutoProvision();

        // This will send ping messages on a continuous
        // loop
        opts.Services.AddHostedService<PingerService>();
    }).RunOaktonCommands(args);
On the Ponger side, I’ve got this setup:
using Baseline.Dates;
using Jasper;
using Jasper.RabbitMQ;
using Oakton;

return await Host.CreateDefaultBuilder(args)
    .UseJasper(opts =>
    {
        // Going to listen to a queue named "pings", but disregard any messages older than
        // 15 seconds
        opts.ListenToRabbitQueue("pings", queue => queue.TimeToLive(15.Seconds()));

        // Configure Rabbit MQ connections and optionally declare Rabbit MQ
        // objects through an extension method on JasperOptions.Endpoints
        opts.UseRabbitMq() // This is short hand to connect locally
            .DeclareExchange("pings", exchange =>
            {
                // Also declares the queue too
                exchange.BindQueue("pings");
            })
            .AutoProvision()

            // Option to blow away existing messages in
            // all queues on application startup
            .AutoPurgeOnStartup();
    })
    .RunOaktonCommands(args);
When running the applications side by side, I’ll get output like this from Pinger:
Got pong #55
info: Jasper.Runtime.JasperRuntime[104]
      Successfully processed message PongMessage#01818741-30c2-4ab7-9fa8-d7870d194754 from rabbitmq://queue/pings
info: Jasper.Runtime.JasperRuntime[204]
      Sending agent for rabbitmq://exchange/pings has resumed
Got pong #56
info: Jasper.Runtime.JasperRuntime[104]
      Successfully processed message PongMessage#01818741-34b3-4d34-910a-c9fc4c191bfc from rabbitmq://queue/pings
info: Jasper.Runtime.JasperRuntime[204]
      Sending agent for rabbitmq://exchange/pings has resumed
and this from Ponger:
Got ping #57
info: Jasper.Runtime.JasperRuntime[104]
      Successfully processed message PingMessage#01818741-389e-4ddd-96cf-fb8a76e4f5f1 from rabbitmq://queue/pongs
info: Jasper.Runtime.JasperRuntime[204]
      Sending agent for rabbitmq://queue/pongs has resumed
Got ping #58
info: Jasper.Runtime.JasperRuntime[104]
      Successfully processed message PingMessage#01818741-3c8e-469f-a330-e8c9e173dc40 from rabbitmq://queue/pongs
info: Jasper.Runtime.JasperRuntime[204]
      Sending agent for rabbitmq://queue/pongs has resumed
and of course, since Jasper is a work in progress, there’s a bunch of erroneous or at least misleading messages about a sending agent getting resumed that I need to take care of…
So what’s in place right now that can be inferred from the code samples above? The Jasper + Rabbit MQ integration today provides:
A way to subscribe to incoming messages from a Rabbit MQ queue. It’s not shown here, but you have all the options you’d expect to configure Rabbit MQ prefetch counts, message handling parallelism, and opt into persistent, inbox messaging
Mechanisms to declare Rabbit MQ queues, exchanges, and bindings as well as the ability to fine tune Rabbit MQ options for these objects
Create declared Rabbit MQ objects at system startup time
Automatically purge old messages out of Rabbit MQ queues on start up. It’s not shown here, but you can do this on a queue by queue basis as well
Create publishing rules from a Jasper process to direct outgoing messages to Rabbit MQ exchanges or directly to queues
What’s also available but not shown here is opt in, conventional routing to route outgoing messages to Rabbit MQ exchanges based on the message type names or to automatically declare and configure subscriptions to Rabbit MQ queues based on the message types of the messages that this process handles. This conventional routing is suspiciously similar (copied from) MassTransit because:
I like MassTransit’s conventional routing functionality
Bi-directional wire compatibility mostly out of the box with MassTransit is a first class goal for Jasper 2.0
Why Rabbit MQ? What about other things?
Jasper has focused on Rabbit MQ as the main transport option out of the box because that’s what my shop already uses (and I’m most definitely trying to get us to use Jasper at work), it has a great local development option through Docker hosting, and frankly because it’s easy to use. Jasper also supports Pulsar of all things, and will definitely have a Kafka integration before 2.0. Other transports will be added based on user requests, and that’s also a good place for other folks to get involved.
I had someone asking about using Jasper with Amazon SQS, and that’s such a simple model, that I might build that out as a reference for other folks.
What’s up next?
Now that I’ve introduced Jasper, its outbox functionality, and its integration with Rabbit MQ, my next post is visiting the utilities baked into Jasper itself for dealing with stateful resources like databases or broker configuration at development and production time. This is going to include a lot of command line functionality baked into your application.
Let me just put this stake into the ground. The combination of Marten and Jasper will quickly become the most productive and lowest ceremony tooling for event sourcing and CQRS architectures on the .NET stack.
And for any George Strait fans out there, this song may be relevant to the previous paragraph:)
CQRS and Event Sourcing
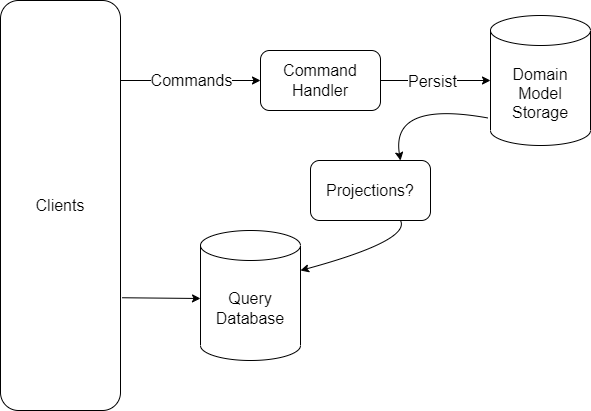
Just to define some terminology, the Command Query Responsibility Separation (CQRS) pattern was first described by Greg Young as an approach to software architecture where you very consciously separate “writes” that change the state of the system from “reads” against the system state. The key to CQRS is to use separate models of the system state for writing versus querying. That leads to something I think of as the “scary view of CQRS”:
The “scary” view of CQRS
The “query database” in my diagram is meant to be an optimized storage for the queries needed by the system’s clients. The “domain model storage” is some kind of persisted storage that’s optimized for writes — both capturing new data and presenting exactly the current system state that the command handlers would need in order to process or validate incoming commands.
Many folks have a visceral, negative reaction to this kind of CQRS diagram as it does appear to be more complexity than the more traditional approach where you have a single database model — almost inevitably in a relational database of some kind — and both reads and writes work off the same set of database tables. Hell, I walked out of an early presentation by Greg Young about what later became to be known as CQRS at QCon 2008 shaking my head thinking this was all nuts.
Here’s the deal though, when we’re writing systems against the one, true database model, we’re potentially spending a lot of time mapping incoming messages to the stored model, and probably even more time transforming the raw database model into a shape that’s appropriate for our system’s clients in a way that also creates some decoupling between clients and the ugly, raw details of our underlying database. The “scary” CQRS architecture arguably just brings that sometimes hidden work and complexity into the light of day.
Now let’s move on to Event Sourcing. Event sourcing is a style of system persistence where each state change is captured and stored as an explicit event object. There’s all sorts of value from keeping the raw change events around for later, but you of course do need to compile the events into derived, or “projected” models that represent the current system state. When combining event sourcing into a CQRS architecture, some projected models from the raw events can serve as both the “write model” inside of incoming commands, while others can be built as the “query model” that clients will use to query our system.
At the end of this section, I want to be clear that event sourcing and CQRS can be used independently of each other, but to paraphrase Forrest Gump, event sourcing and CQRS go together like peas and carrots.
Now, the event sourcing side of this especially might sound a little scary if you’re not familiar with some of the existing tooling, so let’s move on first to Marten…
Marten has a mature feature set for event sourcing already, and we’re grown quite a bit in capability toward our support for projections (read-only views of the raw events). If you’ll peek back at the “scary” view of CQRS above, Marten’s projection support solves the problem of keeping the raw events synchronized to both any kind of “write model” for incoming commands and the richer “query model” views for system clients within a single database. In my opinion, Marten removes the “scary” out of event sourcing and we’re on our way to being the best possible “event sourcing in a box” solution for .NET.
As that support has gotten more capable and robust though, our users have frequently been asking about how to subscribe to events being captured in Marten and how to relay those events reliably to some other kind of infrastructure — which could be a completely separate database, outgoing message queues, or some other kind of event streaming scenario.
Oskar Dudycz and I have been discussing how to solve this in Marten, and we’ve come up with these three main mechanisms for supporting subscriptions to event data:
Some or all of the events being captured by Marten should be forwarded automatically at the time of event capture (IDocumentSession.SaveChangesAsync())
When strict ordering is required, we’ll need some kind of integration into Marten’s async daemon to relay events to external infrastructure
For massive amounts of data with ambitious performance targets, use something like Debezium to directly stream Marten events from Postgresql to Kafka/Pulsar/etc.
Especially for the first item in that list above, we need some kind of outbox integration with Marten sessions to reliably relay events from Marten to outgoing transports while keeping the system in a consistent state (i.e., don’t publish the events if the transaction fails).
Fortunately, there’s a functional outbox implementation for Marten in…
To be clear, Jasper as a project was pretty well mothballed by the combination of COVID and the massive slog toward Marten 4.0 (and then a smaller slog to 5.0). However, I’ve been able to get back to Jasper and yesterday kicked out a new Jasper 2.0.0-alpha-2 release and (Re) Introducing Jasper as a Command Bus.
For this post though, I want to explore the potential of the Jasper + Marten combination for CQRS architectures. To that end, a couple weeks I published Marten just got better for CQRS architectures, which showed some new APIs in Marten to simplify repetitive code around using Marten event sourcing within CQRS architectures. Part of the sample code in that post was this MVC Core controller that used some newer Marten functionality to handle an incoming command:
public async Task CompleteCharting(
    [FromBody] CompleteCharting charting,
    [FromServices] IDocumentSession session)
{
    var stream = await session
        .Events.FetchForExclusiveWriting<ProviderShift>(charting.ShiftId);

    // Validation on the ProviderShift aggregate
    if (stream.Aggregate.Status != ProviderStatus.Charting)
    {
        throw new Exception("The shift is not currently charting");
    }

    // We "decided" to emit one new event
    stream.AppendOne(new ChartingFinished(stream.Aggregate.AppointmentId.Value, stream.Aggregate.BoardId));

    await session.SaveChangesAsync();
}
To review, that controller method:
Takes in a command message of type CompleteCharting
Loads the current state of the aggregate ProviderShift model referred to by the incoming command, and does so in a way that takes care of concurrency for us by waiting to get an exclusive lock on the particular ProviderShift
Assuming that the validation against the ProviderShift succeeds, emits a new ChartingFinished event
Saves the pending work with a database transaction
In that post, I pointed out that there were some potential flaws or missing functionality with this approach:
We probably want some error handling to retry the operation if we hit concurrency exceptions or timeout trying to get the exclusive lock. In other words, we have to plan for concurrency exceptions
It’d be good to be able to automatically publish the new ChartingFinished event to a queue to take further action within our system (or an external service if we were using messaging here)
Lastly, I’d argue there’s some repetitive code up there that could be simplified
To address these points, I’m going to introduce Jasper and its integration with Marten (Jasper.Persistence.Marten) to the telehealth portal sample from my previous blog post.
I’m going to move the actual handling of the CompleteCharting to a Jasper handler shown below that is functionally equivalent to the controller method shown earlier (except I switched the concurrency protection to being optimistic):
// This is auto-discovered by Jasper
public class CompleteChartingHandler
{
    [MartenCommandWorkflow] // this opts into some Jasper middlware
    public ChartingFinished Handle(CompleteCharting charting, ProviderShift shift)
    {
        if (shift.Status != ProviderStatus.Charting)
        {
            throw new Exception("The shift is not currently charting");
        }

        return new ChartingFinished(charting.AppointmentId, shift.BoardId);
    }
}
And the controller method gets simplified down to just relaying the command to Jasper:
    public Task CompleteCharting(
        [FromBody] CompleteCharting charting,
        [FromServices] ICommandBus bus)
    {
        // Just delegating to Jasper here
        return bus.InvokeAsync(charting, HttpContext.RequestAborted);
    }
There’s some opportunity for some mechanisms to make the code above be a little less repetitive and efficient. Maybe by riding on Minimal APIs. That’s for a later date though:)
By using the new [MartenCommandWorkflow] attribute, we’re directing Jasper to surround the command handler with middleware that handles much of the Marten mechanics by:
Loading the aggregate ProviderShift for the incoming CompleteCharting command (I’m omitting some details here for brevity, but there’s a naming convention that can be explicitly overridden to pluck the aggregate identity off the incoming command)
Passing that ProviderShift aggregate into the Handle() method above
Applying the returned event to the event stream for the ProviderShift
Committing the outstanding changes in the active Marten session
The Handle() code above becomes an example of a Decider function. Even better yet, it’s completely decoupled from any kind of infrastructure and fully synchronous. I’m going to argue that this approach will make command handlers much easier to unit test, definitely easier to write, and easier to read later just because you’re only focused on the business logic.
So that covers the repetitive code problem, but let’s move on to automatically publishing the ChartingCompleted event and some error handling. I’m going to add Jasper through the application’s bootstrapping code as shown below:
builder.Host.UseJasper(opts =>
{
    // I'm choosing to process any ChartingFinished event messages
    // in a separate, local queue with persistent messages for the inbox/outbox
    opts.PublishMessage<ChartingFinished>()
        .ToLocalQueue("charting")
        .DurablyPersistedLocally();

    // If we encounter a concurrency exception, just try it immediately
    // up to 3 times total
    opts.Handlers.OnException<ConcurrencyException>().RetryNow(3);

    // It's an imperfect world, and sometimes transient connectivity errors
    // to the database happen
    opts.Handlers.OnException<NpgsqlException>()
        .RetryWithCooldown(50.Milliseconds(), 100.Milliseconds(), 250.Milliseconds());
});
Jasper comes with some pretty strong exception handling policy capabilities you’ll need to do grown up development. In this case, I’m just setting up some global policies in the application to retry message failures on either Marten concurrency exceptions or the inevitable, transient Postgresql connectivity hiccups. In the case of the concurrency exception, you may just need to start the work over to ensure you’re starting from the most recent aggregate changes. I used globally applied policies here, but Jasper will also allow you to override that on a message type by message type basis.
Lastly, let’s add the Jasper outbox integration for Marten and opt into automatic event publishing with this bit of configuration chained to the standard AddMarten() usage:
builder.Services.AddMarten(opts =>
{
    // Marten configuration...
})
    // I added this to enroll Marten in the Jasper outbox
    .IntegrateWithJasper()

    // I also added this to opt into events being forward to
    // the Jasper outbox during SaveChangesAsync()
    .EventForwardingToJasper();
And that’s actually that. The configuration above will add the Jasper outbox tables to the Marten database for us, and let Marten’s database schema management manage those extra database objects.
Back to the command handler (mildly elided):
public class CompleteChartingHandler
{
    [MartenCommandWorkflow]
    public ChartingFinished Handle(CompleteCharting charting, ProviderShift shift)
    {
        // validation code goes here!

        return new ChartingFinished(charting.AppointmentId, shift.BoardId);
    }
}
By opting into the outbox integration and event forwarding to Jasper from Marten, when this command handler is executed, the ChartingFinished events will be published — in this case just to an in-memory queue, but it could also be to an external transport — with Jasper’s outbox implementation that guarantees that the message will be delivered at least once as long as the database transaction to save the new event succeeds.
Conclusion and What’s Next?
There’s a tremendous amount of work in the rear window to get to the functionality that I demonstrated here, and a substantial amount of ambition in the future to drive this forward. I would love any possible feedback both positive and negative. Marten is a team effort, but Jasper’s been mostly my baby for the past 3-4 years, and I’d be happy for anybody who would want to get involved with that. I’m way behind in documentation for Jasper and somewhat for Marten, but that’s in flight.
My next couple posts to follow up on this are to:
Do a deeper dive into Jasper’s outbox and explain why it’s different and arguably more useful than the outbox implementations in other leading .NET tools
Introduce the usage of Rabbit MQ with Jasper for external messaging
Take a detour into the development and deployment time command line utilities built into Jasper & Marten through Oakton
I’m assuming some prior knowledge of Event Sourcing as an architectural pattern here. I highly recommend Oskar Dudycz’s Introduction to Event Sourcing training kit or this video from Derek Comartin. While both Event Sourcing and the closely associated CQRS architectural style are both useful without the other, I’m still assuming here that you’re interested in using Marten for event sourcing within a larger CQRS architecture.
So you’re adopting an event sourcing style with Marten for your persistence within a larger CQRS architectural style. Crudely speaking, all “writes” to the system state involve sending a command message to your CQRS service with a workflow something like this:
In the course of handling the command message, our command handler (or HTTP endpoint) needs to:
Fetch a “write model” that represents the state for the current workflow. This projected “write model” will be used by the command handler to validate the incoming command and also to…
Decide what subsequent events should be published to update the state of the system based on the existing state and the incoming command
Persist the new events to the ongoing Marten event store
Possibly publish some or all of the new events to an outgoing transport to be acted upon asynchronously
Deal with concurrency concerns, especially if there’s any significant chance that other related commands maybe coming in for the same logical workflow at the same time
Do note that as I shift to implementations that I’m going to mostly bypass any discussion of design patterns or what I personally consider to be useless cruft from common CQRS approaches in the .Net or JVM worlds. I.e., no repositories will be used in any of this code.
As an example system, let’s say that we’re building a new, online telehealth system that among other things will track how a medical provider spends their time during a shift helping patients during their workday. Using Marten’s “self-aggregate” support, a simplified version of the provider shift state is represented by this model:
public class ProviderShift
{
    public Guid Id { get; set; }

    // Pay attention to this, this will come into play
    // later
    public int Version { get; set; }

    public Guid BoardId { get; private set; }
    public Guid ProviderId { get; init; }
    public ProviderStatus Status { get; private set; }
    public string Name { get; init; }

    public Guid? AppointmentId { get; set; }

    public static async Task<ProviderShift> Create(ProviderJoined joined, IQuerySession session)
    {
        var provider = await session.LoadAsync<Provider>(joined.ProviderId);
        return new ProviderShift
        {
            Name = $"{provider.FirstName} {provider.LastName}",
            Status = ProviderStatus.Ready,
            ProviderId = joined.ProviderId,
            BoardId = joined.BoardId
        };
    }

    public void Apply(ProviderReady ready)
    {
        AppointmentId = null;
        Status = ProviderStatus.Ready;
    }

    public void Apply(ProviderAssigned assigned)
    {
        Status = ProviderStatus.Assigned;
        AppointmentId = assigned.AppointmentId;
    }

    public void Apply(ProviderPaused paused)
    {
        Status = ProviderStatus.Paused;
        AppointmentId = null;
    }

    // This is kind of a catch all for any paperwork the
    // provider has to do after an appointment has ended
    // for the just concluded appointment
    public void Apply(ChartingStarted charting) => Status = ProviderStatus.Charting;
}
Next up, let’s play the user story for a provider to make their “charting” activity complete after a patient appointment concludes. Looking at the sequence diagram and the bullet list of concerns for each command handler, we’ve got a few things to worry about. Never fear though, because Marten has you (mostly) covered today with a couple new features introduced in Marten v5.4 last week.
Starting with this simple command:
public record CompleteCharting(
    Guid ShiftId,
    Guid AppointmentId,
    int Version);
We’ll use Marten’s brand new IEventStore.FetchForWriting<T>() API to whip up the basic command handler (just a small ASP.Net Core Controller endpoint):
    public async Task CompleteCharting(
        [FromBody] CompleteCharting charting,
        [FromServices] IDocumentSession session)
    {
        /* We've got options for concurrency here! */
        var stream = await session
            .Events.FetchForWriting<ProviderShift>(charting.ShiftId);

        // Validation on the ProviderShift aggregate
        if (stream.Aggregate.Status != ProviderStatus.Charting)
        {
            throw new Exception("The shift is not currently charting");
        }

        // We "decided" to emit one new event
        stream.AppendOne(new ChartingFinished(stream.Aggregate.AppointmentId.Value, stream.Aggregate.BoardId));

        await session.SaveChangesAsync();
    }
The FetchForWriting() method used above is doing a couple different things:
Finding the current, persisted version of the event stream for the provider shift and loading that into the current document session to help with optimistic concurrency checks
Fetching the current state of the ProviderShift aggregate for the shift id coming up on the command. Note that this API papers over whether or not the aggregate in question is a “live aggregate” that needs to be calculated on the fly from the raw events or previously persisted as just a Marten document by either an inline or asynchronous projection. I think I would strongly recommend that “write model” aggregates be either inline or live to avoid eventual consistency issues.
Concurrency?!?
Hey, the hard truth is that it’s easy for the command to be accidentally or incidentally dispatched to your service multiple times from messaging infrastructure, multiple users doing the same action in different sessions, or somebody clumsy like me just accidentally clicking a button too many times. One way or another, we may need to harden our command handler against concurrency concerns.
The usage of FetchForWriting<T>() will actually set you up for optimistic concurrency checks. If someone else manages to successfully process a command against the same provider shift between the call to FetchForWriting<T>() and IDocumentSession.SaveChangesAsync(), you’ll get a Marten ConcurrencyException thrown by SaveChangesAsync() that will abort and rollback the transaction.
Moving on though, let’s tighten up the optimistic version check by first telling Marten what the version of the provider shift was that our command thinks that the provider shift is at on the server. First though, we need to get the current version back to the client that’s collecting changes to our provider shift. If you scan back to the ProviderShift aggregate above, you’ll see this property:
public int Version { get; set; }
With another new little feature in Marten v5.4, the Marten projection support will automatically set the value of a Version to the latest stream version for a single stream aggregate like the ProviderShift. Knowing that, and assuming that ProviderShift is updated inline, we could just deliver the whole ProviderShift to the client with this little web service endpoint (using Marten.AspNetCore extensions):
The Version property can be a field, scoped as internal, or read-only. Marten is using a dynamically generated Lambda that can happily bypass whatever scoping rules you have to set the version to the latest event for the stream represented by this aggregate. The Version naming convention can also be explicitly ignored, or redirected to a totally differently named member. Lastly, it can even be a .Net Int64 type too — but if you’re doing that, you probably have some severe modeling issues that should be addressed first!
Back to our command handler. If the client has what’s effectively the “expected starting version” of the ProviderShift and sends the CompleteCharting command with that version, we can change the first line of our handler method code to this:
        var stream = await session

            // Note: I'm passing in the expected, starting provider shift
            // version from the command
            .Events.FetchForWriting<ProviderShift>(charting.ShiftId, charting.Version);
This new version will throw a ConcurrencyException right off the bat if the expected, starting version is not the same as the last, persisted version in the database. After that, it’s the same optimistic concurrency check at the point of calling SaveChangesAsync() to commit the changes.
Lastly, since Marten is built upon a real database instead of trying to be its own specialized storage engine like many other event sourcing tools, we’ve got one last trick. Instead of putzing around with optimistic concurrency checks let’s go to a pessimistic, exclusive lock on the specific provider shift so that only one session at a time can ever be writing to that provider shift with this variation:
        var stream = await session

            // Note: This will try to "wait" to claim an exclusive lock for writing
            // on the provider shift event stream
            .Events.FetchForExclusiveWriting<ProviderShift>(charting.ShiftId);
As you can see, Marten has some new functionality to make it even easier to use Marten within CQRS architectures by eliminating some previously repetitive code in both queries on projected state and in command handlers where you need to use Marten’s concurrency control.
Wait, not so fast, you missed some things!
I missed a couple very big things in the sample code above. For one, we’d probably want to broadcast the new events through some kind of service bus to allow other systems or just our own system to asynchronously do other work (like trying to assign our provider to another ready patient appointment). To do that reliably so that the event capture and the outgoing events being published succeed or fail together in one atomic action, I really need an “outbox” of some sort integrated into Marten.
I also left out any kind of potential error handling or message retry capabilities around the concurrency exceptions. And lastly (that I can think of offhand), I completely left out any discussion of the instrumentation you’d want in any kind of grown up system.
Since we’re in the middle of the NBA playoffs, I’m reminded of a Shaquille O’Neal quote from when his backup was Alonzo Mourning, and Mourning had a great game off the bench: “sometimes Superman needs some help from the Incredible Hulk.” In this case, part of the future of Marten is to be combined with another project called Jasper that is going to add external messaging with a robust outbox implementation for Marten to create a full stack for CQRS architectures. Maybe as soon as late next week or at least in June, I’ll write a follow up showing the Marten + Jasper combination that deals with the big missing pieces of this post.
I’m going to have to admit that I got caught flat footed by the .Net 6 release a couple weeks ago. I hadn’t really been paying much attention to the forthcoming changes, maybe got cocky by how easy the transition from netcoreapp3.1 to .Net 5 was, and have been unpleasantly surprised by how much work it’s going to take to move some OSS projects up to .Net 6. All at the same time that the advance users of the world are clamoring for all their dependencies to target .Net 6 yesterday.
All that being said, here’s my running list of plans to get the projects in the JasperFx GitHub organization successfully targeting .Net 6. I’ll make edits to this page as things get published to Nuget.
Baseline
Baseline is a grab bag utility library full of extension methods that I’ve relied on for years. Nobody uses it directly per se, but it’s a dependency of just about every other project in the organization, so it went first with the 3.2.2 release adding a .Net 6 target. No code changes were necessary other than adding .Net 6 to the CI testing. Easy money.
Oakton
EDIT: Oakton v4.0 is up on Nuget. WebApplication is supported, but you can’t override configuration in commands with this model like you can w/ HostBuilder only. I’ll do a follow up at some point to fill in this gap.
Oakton is a tool to add extensible command line options to .Net applications based on the HostBuilder model. Oakton is my problem child right now because it’s a dependency in several other projects and its current model does not play nicely with the new WebApplicationBuilder approach for configuring .Net 6 applications. I’d also like to get the Oakton documentation website moved to the VitePress + MarkdownSnippets model we’re using now for Marten and some of the other JasperFx projects. I think I’ll take a shortcut here and publish the Nuget and let the documentation catch up later.
Alba
Alba is an automated testing helper for ASP.Net Core. Just like Oakton, Alba worked very well with the HostBuilder model, but was thrown for a loop with the new WebApplicationBuilder configuration model that’s the mechanism for using the new Minimal API (*cough* inevitable Sinatra copy *cough*) model. Fortunately though, Hawxy came through with a big pull request to make Alba finally work with the WebApplicationFactory model that can accommodate the new WebApplicationBuilder model, so we’re back in business soon. Alba 5.1 will be published soon with that work after some documentation updates and hopefully some testing with the Oakton + WebApplicationBuilder + Alba model.
EDIT: Alba 7.0 is up with the necessary changes, but the docs will come later this week
Lamar
Lamar is an IoC/DI container and the modern successor to StructureMap. The biggest issue with Lamar on v6 was Nuget dependencies on the IServiceCollection model, plus needing some extra implementation to light up the implied service model of Minimal APIs. All the current unit tests and even integration tests with ASP.Net Core are passing on .Net 6. To finish up a new Lamar 7.0 release is:
One .Net 6 related bug in the diagnostics
Better Minimal API support
Upgrade Oakton & Baseline dependencies in some of the Lamar projects
Documentation updates for the new IAsyncDisposable support and usage with WebApplicationBuilder with or without Minimal API usage
EDIT: Lamar 7.0 is up on Nuget with .Net 6 support
Marten/Weasel
We just made the gigantic V4 release a couple months ago knowing that we’d have to follow up quickly with a V5 release with a few breaking changes to accommodate .Net 6 and the latest version of Npgsql. We are having to make a full point release, so that opens the door for other breaking changes that didn’t make it into V4 (don’t worry, I think shifting from V4 to V5 will be easy for most people). The other Marten core team members have been doing most of the work for this so far, but I’m going to jump into the fray later this week to do some last minute changes:
Review some internal changes to Npgsql that might have performance impacts on Marten
Consider adding an event streaming model within the new V4 async daemon. For folks that wanna use that to publish events to some kind of transport (Kafka? Some kind of queue?) with strict ordering. This won’t be much yet, but it keeps coming up so we might as well consider it.
Multi-tenancy through multiple databases. It keeps coming up, and potentially causes breaking API changes, so we’re at least going to explore it
I’m trying not to slow down the Marten V5 release with .Net 6 support for too long, so this is all either happening really fast or not at all. I’ll blog more later this week about multi-tenancy & Marten.
Weasel is a spin off library from Marten for database change detection and ADO.Net helpers that are reused in other projects now. It will be published simultaneously with Marten.
Jasper
Oh man, I’d love, love, love to have Jasper 2.0 done by early January so that it’ll be available for usage at my company on some upcoming work. This work is on hold while I deal with the other projects, my actual day job, and family and stuff.
Starting next week I’ll be doing some more deep dives into new Marten V4 improvements and some more involved sample usages.
Today I’m very excited to announce the official release of Marten V4.0! The Nugets just went live, and we’ve published out completely revamped project website at https://martendb.io.
This has been at least a two year journey of significant development effort by the Marten core team and quite a few contributors, preceded by several years of brainstorming within the Marten community about the improvements realized by this release. There’s plenty more to do in the Marten backlog, but I think this V4 release puts Marten on a very solid technical foundation for the long term future.
This was a massive effort, and I’d like to especially thank the other core team members Oskar Dudycz for answering so many user questions and being the champion for our event sourcing feature set, and Babu Annamalai for the newly improved website and all our grown up DevOps infrastructure. Their contributions over the years and especially on this giant release have been invaluable.
I’d also like to thank:
JT for taking on the nullability sweep and many other things
Ville Häkli might have accidentally become our best tester and helped us discover and deal with several issues along the way
Julien Perignon and his team for their patience and help with the Marten V4 shakedown cruise
Barry Hagan started the ball rolling with Marten’s new, expanded metadata collection
Raif Atef for several helpful bug reports and some related fixes
Simon Cropp for several pull requests and doing some dirty work
Kasper Damgård for a lot of feedback on Linq queries and memory usage
Adam Barclay helped us improve Marten’s multi-tenancy support and its usability
and many others who raised actionable issues, gave us feedback, and even made code contributions. Keeping in mind that I personally grew up on a farm in the middle of nowhere in the U.S., it’s a little mind-blowing to me to work on a project of this magnitude that at a quick glance included contributors from at least five continents on this release.
One of my former colleagues at Calavista likes to ask prospective candidates for senior architect roles what project they’ve done that they’re the most proud of. I answered “Marten” at the time, but I think I mean that even more now.
What Changed in this Release?
To quote the immortal philosopher Ferris Bueller:
The question isn‘t ‘what are we going to do’, the question is ‘what aren’t we going to do? ‘
We did try to write up a list of breaking changes for V4 in the migration guide, but here’s some highlights:
We generally made a huge sweep of the Marten code internals looking for every possible opportunity to reduce object allocations and dictionary lookups for low level performance improvements. The new dynamic code generation approach in Marten helped get us to that point.
We think Marten is even easier to bootstrap in new projects with improvements to the IServiceCollection.AddMarten() extensions
Marten supports System.Text.Json — but use that with some caution of course
The Linq support took a big step forward with a near rewrite and filled in some missing support for better querying through child collections as a big example. The Linq support is now much more modular and we think that will help us continue to grow that support. It’s a small thing, but the Linq parsing was even optimized a little bit for performance
Event Sourcing in Marten got a lot of big improvements that were holding up adoption by some users, especially in regards to the asynchronous projection support. The “async daemon” was completely rewritten and is now much easier to incorporate into .Net systems.
As a big user request, Marten supports much more options for tracking flexible metadata like correlation ids and even user defined headers in both document and event storage
Multi-tenancy support was improved
Soft delete support got some additional usability features
PLv8 adoption has been a stumbling block, so all the features related to PLv8 were removed to a separate add-on library called Marten.PLv8
The schema management features in Marten made some significant strides and should be able to handle more scenarios with less manual intervention — we think/hope/let’s just be positive for now
What’s Next for Marten?
Full point OSS releases inevitably bring a barrage of user reported errors, questions about migrating, possibly confusing wording in new documentation, and lots of queries about some significant planned features we just couldn’t fit into this already giant release. For that matter, we’ll probably have to quickly spin out a V5 release for .Net 6 and Npgsql 6 because there’s breaking changes coming due to those dependencies. OSS projects are never finished, only abandoned, and there’ll be a world of things to take care of in the aftermath of 4.0 — but for right now, Don’t Steal My Sunshine!.
We’re genuinely close to finally pulling the damn trigger on Marten V4. One of the last things I’m coding for the release is a new recipe for users to write very efficient web services backed by Marten database storage.
A Traditional .Net Approach
Before I get into the exact mechanics of that, let’s set the stage a little bit and draw some contrasts with a more traditional .Net web service stack. Let’s start by saying that in that traditional stack, you’re not using any kind of CQRS and the system state is persisted in the “one true model” approach using Entity Framework Core and an RDBMS like Sql Server. Now, in some web services you need to query data from the database and serve up a subset of that data into the outgoing HTTP response in a web service endpoint. The typical flow — with a focus on what’s happening under the covers — would be to:
ASP.Net Core receives an HTTP GET, finds the proper endpoint, and calls the right handler for that route. Not that it actually matters, but let’s assume the endpoint handler is an MVC Core Controller method
ASP.Net Core invokes a call to your DI container to build up the MVC controller object, and calls the right method for the route
You’ve been to .Net conferences and internalized the idea that an MVC controller shouldn’t get too big or do things besides HTTP mediation, so you’re delegating to a tool like MediatR. MediatR itself is going to go through another DI container service resolution to find the right handler for the input model, then invoke that handler
EF Core issues a query against your Sql Server database. If you’re needing to fetch data on more than just the root aggregate model, the query is going to be an outer join against all the child tables too
EF Core loops around in the database rows and creates objects for your .Net domain model classes based on its ORM mappings
You certainly don’t want to send the raw domain model on the wire because of coupling concerns, or don’t want every bit of data exposed to the client in a particular web service, so you use some kind of tool like AutoMapper to transform the internal domain model objects built up by EF Core into Data Transfer Objects (DTO) purposely designed to go over the wire.
Lastly, you return the outgoing DTO model, which is serialized to JSON and sent down the HTTP response by MVC Core
Sound pretty common? That’s also a lot of overhead. A lot of memory allocations, data mappings between structures, JSON serialization, and a lot of dictionary lookups just to get data out of the database and spit it out into the HTTP response. It’s also a non-trivial amount of code, and I’d argue that some of the tools I mentioned are high ceremony.
Now do CQRS!
I initially thought of CQRS as looking like a whole lot more work to code, and that’s not an uncommon impression when folks are first introduced to it. I’ve come to realize over time that it’s not really more work so much as it’s really just doing about the same amount of work in different places and different times in the application’s workflow.
Now let’s at least introduce CQRS into our application architecture. I’m not saying that that automatically implies using event sourcing, but let’s say that you are writing a pre-built “read side” model of the state of your system directly to a database of some sort. Now from that same web service I was describing before, you just need to fetch that persisted “read side” model from the database and spit that state right out to the HTTP response.
Now then, I’ve just yada, yada’d all the complexity of the CQRS architecture that continuously updates the read side view for you, but hey, Marten does that for you too and that can be a shortly forthcoming follow up blog post.
Finally bringing Marten V4 into play, let’s say our read side model for an issue tracking system looks like this:
    public class Note
    {
        public string UserName { get; set; }
        public DateTime Timestamp { get; set; }
        public string Text { get; set; }
    }

    public class Issue
    {
        public Guid Id { get; set; }
        public string Description { get; set; }
        public bool Open { get; set; }

        public IList<Note> Notes { get; set; }
    }
Before anyone gets bent out of shape by this, it’s perfectly possible to tell Marten to serialize the persisted documents to JSON with camel or even snake casing to be more idiomatic JSON or Javascript friendly.
Now, let’s build out two controller endpoints, one that gives you an Issue payload by searching by its id, and a second endpoint that gives you all the open Issue models in a single JSON array payload. That controller — using some forthcoming functionality in a new Marten.AspNetCore Nuget — looks like this:
    public class GetIssueController: ControllerBase
    {
        private readonly IQuerySession _session;

        public GetIssueController(IQuerySession session)
        {
            _session = session;
        }

        [HttpGet("/issue/{issueId}")]
        public Task Get(Guid issueId)
        {
            // This "streams" the raw JSON to the HttpResponse
            // w/o ever having to read the full JSON string or
            // deserialize/serialize within the HTTP request
            return _session.Json
                .WriteById<Issue>(issueId, HttpContext);
        }

        [HttpGet("/issue/open")]
        public Task OpenIssues()
        {
            // This "streams" the raw JSON to the HttpResponse
            // w/o ever having to read the full JSON string or
            // deserialize/serialize within the HTTP request
            return _session.Query<Issue>()
                .Where(x => x.Open)
                .WriteArray(HttpContext);
        }
In the GET: /issue/{issueId} endpoint, you’ll notice the call to the new IQuerySession.Json.WriteById() extension method, and how I’m passing to it the current HttpContext. That method is:
Executing a database query against the underlying Postgresql database. And in this case, all of the data is stored in a single column in a single row, so there’s not JOINs or sparse datasets like there would be with an ORM querying an object that has child collections.
Write the raw bytes of the persisted JSON data directly to the HttpResponse.Body without ever bothering to write the whole thing to a .Net string and definitely without having to incur the overhead of JSON deserialization/serialization. That extension method also sets the HTTP content-length and content-type response headers, as well as setting the HTTP status code to 200 if the document is found, or 404 if the data is not found.
In the second HTTP endpoint for GET: /issue/open, the call to WriteArray(HttpContext) is doing something very similar, but writing the results as a JSON array.
By no means is this technique going to be applicable to every HTTP GET endpoint, but when it does, this is far, far more efficient and simpler to code than the more traditional approach that involves all the extra pieces and just has so much more memory allocations and hardware operations going on just to shoot some JSON down the wire.
For a little more context, here’s a test against the /issue/{issueId} endpoint, with a cameo from Alba to help me test the HTTP behavior:
        [Fact]
        public async Task stream_a_single_document_hit()
        {
            var issue = new Issue {Description = "It's bad", Open = true};

            var store = theHost.Services.GetRequiredService<IDocumentStore>();
            using (var session = store.LightweightSession())
            {
                session.Store(issue);
                await session.SaveChangesAsync();
            }

            var result = await theHost.Scenario(s =>
            {
                s.Get.Url($"/issue/{issue.Id}");
                s.StatusCodeShouldBeOk();
                s.ContentTypeShouldBe("application/json");
            });

            var read = result.ReadAsJson<Issue>();

            read.Description.ShouldBe(issue.Description);
        }
Starting yesterday, all of my content about automated testing is curated under the new Automated Testing page on this site.
I kicked off a new blog series yesterday with Integration Testing: IHost Lifecycle with xUnit.Net. I started by just discussing how to manage the lifecycle of a .Net IHost inside of an xUnit.Net testing library. I used xUnit.Net because I’m much more familiar with that library, but we mostly use NUnit for our testing at MedeAnalytics, so I’m going to see how the IHost lifecycle I discussed and demonstrated last time in xUnit.NEt could work in NUnit.
To catch you up from the previous post, I have two projects:
An ASP.Net Core web service creatively named WebApplication. This web service has a small endpoint that allows you to post an array of numbers that returns a response telling you the sum and product of those numbers. The code for that controller action is shown in my previous post.
With NUnit, I chose to use the SetupFixture construct to manage and share the IHost for the test suite like this:
    [SetUpFixture]
    public class Application
    {
        // Make this lazy so you don't build it out
        // when you don't need it.
        private static readonly Lazy<IAlbaHost> _host;

        static Application()
        {
            _host = new Lazy<IAlbaHost>(() => Program
                .CreateHostBuilder(Array.Empty<string>())
                .StartAlba());
        }

        public static IAlbaHost AlbaHost => _host.Value;

        // I want to expose the underlying Lamar container for some later
        // usage
        public static IContainer Container => (IContainer)_host.Value.Services;

        // Make sure that NUnit will shut down the AlbaHost when
        // all the projects are finished
        [OneTimeTearDown]
        public void Teardown()
        {
            if (_host.IsValueCreated)
            {
                _host.Value.Dispose();
            }
        }
    }
With the IHost instance managed by the Application static class above, I can consume the Alba host in an NUnit test like this:
    public class sample_integration_fixture
    {
        [Test]
        public async Task happy_path_arithmetic()
        {
            // Building the input body
            var input = new Numbers
            {
                Values = new[] {2, 3, 4}
            };

            var response = await Application.AlbaHost.Scenario(x =>
            {
                // Alba deals with Json serialization for us
                x.Post.Json(input).ToUrl("/math");

                // Enforce that the HTTP Status Code is 200 Ok
                x.StatusCodeShouldBeOk();
            });

            var output = response.ReadAsJson<Result>();
            output.Sum.ShouldBe(9);
            output.Product.ShouldBe(24);
        }
    }
And now a couple notes about what I did in Application:
I think it’s important to create the IHost lazily, so that you don’t incur the cost of spinning up the IHost when you might be running other tests in your suite that don’t need the IHost. Rapid developer feedback is important, and that’s an awfully easy optimization that could pay off.
The static Teardown() method is decorated with the `[OneTimeTearDown]` attribute to direct NUnit to call that method after all the tests are executed. I cannot stress enough how important it is to clean up resources in your test harness to ensure your ability to quickly iterate through subsequent test runs.
NUnit has a very different model for parallelization than xUnit.Net, and it’s completely “opt in”, so I think there’s less to worry about on that front with NUnit.
At this point I don’t think I have a hard opinion about xUnit.Net vs. NUnit, and I certainly wouldn’t bother switching an existing project from one to the other (even though I’ve certainly done that plenty of times in the past). I haven’t thought this one through enough, but I still think that xUnit.Net is a little bit cleaner for unit testing, but NUnit might be better for integration testing because it gives you finer grained control over fixture lifecycle and has some built in support for test timeouts and retries. At one point I had high hopes for Fixie as another alternative, and that project has become active again, but it would have a long road to challenge either of the two now mainstream tools.
What’s Next?
This series is meant to support my colleagues at MedeAnalytics, so it’s driven by what we just happen to be talking about at any given point. Tomorrow I plan to put out a little post on some Lamar-specific tricks that are helpful in integration testing. Beyond that, I think dealing with database state is the most important thing we’re missing at work, so that needs to be a priority.
I’m part of an initiative at work to analyze and ultimately improve our test automation practices. As part of that work, I’ll be blogging quite a bit about test automation starting with my brain dump on test automation last week and my most recent post on mocks and stubs last month. From here on out, I’m curating all of my posts and selected writings from other folks on my new Automated Testing page.
I’m already on record as saying that the generic host (IHost) in recent versions of .Net is one of the best things that’s ever happened to the .Net ecosystem. In my previous post I stated that I strongly prefer having the system under test running in process with the test harness for faster feedback cycles and easier debugging. The generic host builder introduced in .Net Core turns out to be a very effective way to bootstrap your system within automated test harnesses.
Before I dive into how to use the IHost in automated testing, here’s a couple issues I think you have to address in your integration testing strategy before we go willy nilly spinning up an IHost:
You ideally want to test against your code running in a realistic way, so the way code is bootstrapped and configured should be relatively close to how that code is started up in the real application.
There will inevitably need to be at least some configuration that needs to be different in testing or some services — usually accessing resources external to your system — that need to be replaced with stubs or some other kind of fake implementation.
It’s important to cleanly dispose or shutdown any IHost object you create in memory to avoid potential locks of resources like database connections, files, or ports. Failing to clean up resources in tests can easily make it harder to iterate through test fixes if you find yourself needing to manually kill processes or restart your IDE to release locked resources (been there, done that).
The IHost can be expensive to build up, and sometimes there’s going to be some serious benefit in reusing the IHost between tests to make the test suite run faster.
But the IHost is stateful, and there could easily be resources (singleton scoped services, databases, and whatnot) that could impact later test runs in the suite.
Before I jump into solutions, let’s assume that I have two projects:
WebApplication is an ASP.Net Core web service project. WebApplication uses Lamar as its underlying DI container.
A test project that references WebApplication
xUnit.Net Mechanics
I’m more comfortable with xUnit.Net, so I’m going to use that first. My typical usage is to share the IHost through xUnit.Net’s CollectionFixture mechanism (and if you think the usage of this thing is confusing, welcome to the club). First up, I’ll build out a new class I usually call AppFixture to manage the lifecycle of the IHost. The example project I’ve built here is an ASP.Net Core web service project, so I’m going to use Alba to wrap the host inside of AppFixture as shown below:
    public class AppFixture : IDisposable, IAsyncLifetime
    {
        public IAlbaHost Host { get; private set; }
        public async Task InitializeAsync()
        {
            // Program.CreateHostBuilder() is the code from the WebApplication
            // that configures the HostBuilder for the system
            Host = await Program
                .CreateHostBuilder(Array.Empty<string>())

                // This extension method starts up the underlying IHost,
                // but Alba replaces Kestrel with a TestServer and
                // wraps the IHost
                .StartAlbaAsync();
        }

        public Task DisposeAsync()
        {
            return Host.StopAsync();
        }

        public void Dispose()
        {
            Host?.Dispose();
        }
    }
A couple things to note in that code above:
As we’ll set up next, that class above will be constructed once in memory by xUnit and shared between test fixture classes
The Dispose() and DisposeAsync() methods both dispose the IHost. By normal .Net mechanics, that will also dispose the underlying Lamar IoC container, which will in turn dispose any services created by Lamar at runtime that implement IDisposable. Disposing the IHost also stops any registered IHostedService services that your application may be using for long running tasks (for my colleagues who may be reading this, both NServiceBus and MassTransit start and stop their message listeners in an IHostedService, so that might be in use even if you don’t explicitly use that technique).
Next, we’ll set up AppFixture to be shared between our integration test classes by using the [CollectionDefinition] attribute on a marker class:
    [CollectionDefinition("Integration")]
    public class AppFixtureCollection : ICollectionFixture<AppFixture>
    {

    }
Lastly, I like to build out a base class for integration tests like this one:
    [Collection("Integration")]
    public abstract class IntegrationContext
    {
        protected IntegrationContext(AppFixture fixture)
        {
            theHost = fixture.Host;

            // I am using Lamar as the underlying DI container
            // and want some Lamar specific things later on
            // in the tests
            Container = (IContainer)fixture.Host.Services;
        }

        public IAlbaHost theHost { get; }

        public IContainer Container { get; }
    }
The [Collection] attribute is meaningful here because that makes xUnit.Net run all the tests that are contained in test fixture classes that inherit from IntegrationContext in a single thread so we don’t have to worry about concurrent test runs.*
And finally to bring this all together, let’s say that WebApplication has this simplistic web service code to do some arithmetic:
    public class Result
    {
        public int Sum { get; set; }
        public int Product { get; set; }
    }

    public class Numbers
    {
        public int[] Values { get; set; }
    }

    public class ArithmeticController : ControllerBase
    {
        [HttpPost("/math")]
        public Result DoMath([FromBody] Numbers input)
        {
            var product = 1;
            foreach (var value in input.Values)
            {
                product *= value;
            }

            return new Result
            {
                Sum = input.Values.Sum(),
                Product = product
            };
        }
    }
In the next code block, let’s finally see a test fixture class that uses the new IntegrationContext as a base class and tests the HTTP endpoint shown in the block above.
    public class ArithmeticApiTests : IntegrationContext
    {
        public ArithmeticApiTests(AppFixture fixture) : base(fixture)
        {
        }

        [Fact]
        public async Task post_to_a_secured_endpoint_with_jwt_from_extension()
        {
            // Building the input body
            var input = new Numbers
            {
                Values = new[] {2, 3, 4}
            };

            var response = await theHost.Scenario(x =>
            {
                // Alba deals with Json serialization for us
                x.Post.Json(input).ToUrl("/math");

                // Enforce that the HTTP Status Code is 200 Ok
                x.StatusCodeShouldBeOk();
            });

            var output = response.ReadAsJson<Result>();
            output.Sum.ShouldBe(9);
            output.Product.ShouldBe(24);
        }
    }
Alright, at this point we’ve got a way to shared the system’s IHost in tests for better efficiency, and we’re making sure that all the resources in the IHost are cleaned up when the test suite is done. We’re using the WebApplication’s exact configuration for the IHost, but we still might need to alter that in testing. And there’s also the issue of needing to roll back state in our system between tests. I’ll pick up those subjects in my next couple posts, as well as using NUnit instead of xUnit.Net because that’s what the majority of code at my work uses for testing.
* It would be nice to be able to run parallel tests using our shared IHost, but that can often be problematic because of shared state, so I generally bypass test parallelization in integrated tests. The subject of parallelizing integration tests is worthy of a later blog post of some thoughts I haven’t quite elucidated yet.
I’m strictly talking about automated testing in this post. I’m more or less leading an effort at work to improve our test automation and Test Driven Development practices at work, so I’ll be trying to blog quite a bit about related topics in the next couple months. After reviewing quite a bit of in flight code, I think I’ll try to revisit some of my old blog posts on testability design from the CodeBetter days and update those old lessons from the early days of TDD to what we’re building now.
My company builds and maintains several long running software systems with a healthy back log of feature requests, performance improvements, and stories to retire technical debt. All that is to say that we’re constantly adding to or improving existing code — which implies we’re always running some non-zero risk of creating regression defects. To keep everybody’s stress levels down, we’re taking incremental steps toward a true continuous delivery model where we can smoothly and consistently build and deploy fully tested features while being confident that we aren’t introducing regression defects.
As you’d likely guess, we’re very interested in improving our automated testing practices as a safety net to enable continuous delivery while also improving our quality in general. That leads to the next question, what kind of automated testing should we be doing? Followed by, is there automated testing we’re doing today that isn’t delivering enough bang for the buck?
To that point, let’s take a look at the classic idea of the testing pyramid at some point, as shown below:
The thinking behind the testing pyramid is that there’s a certain, healthy mix of different sorts of automated tests that efficiently lead to better results. I say a “mix” here because unit tests, though relatively cheap compared to other tests, cannot detect many defects that only come out during integration between components, code modules, or systems. From a quick search, I found worlds of memes along the lines of this one:
No integration tests, but all the unit tests pass!
To address exactly what kind of automated tests we should be writing, here’s a stream of consciousness brain dump that I later organized with a patina of organization:
On End to End User Interface Tests
Any kind of test that uses a tool like Selenium to do end to end, black-box testing is going to run slowly. These tests are also frequently be unstable because of asynchronous timing issues in modern browser applications. There’s an unhealthy tendency in many shops who adopt Selenium as a test automation solution to use it as their golden hammer to the exclusion of other testing techniques that can be much more efficient in certain circumstances. To put it bluntly, it’s very difficult to successfully author and maintain test automation suites based on Selenium against complicated applications. In my experience in shops that have attempted large scale Selenium usage, I do not believe that the benefits of those tests have ever outweighed the costs.
I would still recommend using some small number of end to end tests with a tool like Selenium, but those tests should be focused on proving out integration mechanisms between a user interface and backing server side code. For example, I’ve been working on a new integration of Open Id Connect (OIDC) authentication into our web services and web applications. I’ve used Playwright to automate browser testing to prove out the interactions and redirects between the OIDC service and our applications or services.
I also find Cypress.io interesting, but more for doing integration testing of our Angular applications by themselves with a dummy backend. For true end to end testing of .Net-backed web applications, I think I’m interested in replacing Selenium from here on out with Playwright as I think and hope it just does much more for you to make performant and reliable automated tests compared to Selenium.
Driving a browser should not be used to automate functional testing of business logic or data services or any kind of data analysis that could possibly be tested without using the full browser.
If you insist on trying to do a lot of browser automation testing, you better invest in collecting diagnostic information in test runs that can be used by developers to debug test failures. Ideally, I like to have the application’s log output correlated to the test run somehow. I’ve worked with teams that were able to pipe the console.log() tracing from the JavaScript code running in the browser to the test results and that was extremely helpful. Taking screenshots as part of the test can certainly help. As another ideal, I very strongly recommend that any kind of browser automation tests be executable by developers on their local machine on demand for easier debugging. More on this later.
Again, if you absolutely have to write Selenium/Playwright/Cypress tests despite all of my warnings, I strongly recommend you write those tests in the same programming language as the real application. That statement is going to be controversial if any real test automation engineers stumble into this post, but I think it’s important to make it as easy as possible for developers to collaborate with test automation engineers. Moreover, I despise the kind of shadow data access layers you can get from test automation code doing their own thing to write to and read from the underlying data store of the system under test. I think it’s less likely to get that kind of insidious, hidden code duplication if the test code is written in the same programming language and even uses the system’s own data access code to set up or verify database state as part of the automated tests.
Choosing Solitary/Unit Tests or Sociable/Integration Tests
I missed out on this when it was first published, but I think I like the nomenclature of solitary vs sociable tests better than thinking about unit vs integration tests. I also encourage folks to think of that as a continuum rather than a hard categorization. Moreover, I recommend that you switch between solitary and sociable tests even within the same test library where one or the other is more effective.
I would recommend organizing tests by functional area first, and only consider separating out integration tests into a separate testing project when it’s advantageous to use a “fast test, slow test” division for more efficient development.
We have formal requirements for test coverage metrics in our continuous integration builds, so I’d definitely make sure that any integration tests count toward that coverage number.
I think an emphasis on always writing classical unit tests can easily create a strong coupling between the production code and your testing code. That can and will reduce your ability to evolve your code, add new functionality, or do performance optimizations without rewriting your tests.
In many cases, integration tests that start at a natural sub-system facade or a logical controller/conductor entry point will do much better for you as a regression safety net to allow you to refactor your code to allow for new behavior or do important performance optimizations.
Case in point, I relied strictly on fine grained unit tests in my early work in StructureMap, and I definitely felt the negative consequences of that approach (I gave a talk about it in 2008 that’s still relevant). With later releases of StructureMap and now with Lamar, I lean much more heavily on integrated acceptance tests (let’s go ahead and call it Behavior Driven Development) that test from the entry point of the library down and focus on user-centric scenarios. I feel like that testing approach has led to much better results — both in the ease of adding new features, detecting regression defects in automated builds, and allowing me to evolve the functionality of the library.
On the other hand, integration tests can be harder to troubleshoot when they fail because you have more ground to cover. They also run slower of course. If you find that your feedback cycles feel too slow to efficiently run the tests continuously or especially if you find yourself doing long, marathon sessions in your debugger, stop and consider introducing more fine-grained tests first.
Running the Tests Locally vs Remotely
To the previous point, I think it’s critical that developers should be able to easily spin up and run automated integration tests on demand on their local development boxes. Tests will fail, and being able to easily troubleshoot a failing test is a prerequisite for successful test automation. If you can run an integration test locally, you’re much more likely to be able to iterate and try potential fixes quickly. There’s also the very real possibility of attaching a debugger to the testing process.
I think that our current technology set makes it much easier to do integration testing than it was when I was first getting started and the strict Michael Feathers definition of a unit test was in vogue. Just speaking from my own experience, the current .Net 5 generation is very easy to spin up and down in process for automated testing. Docker has been a great way to stand up development environments using Sql Server, Postgresql, Rabbit MQ, and other infrastructural tools.
As a follow up to the previous section, it’s also advantageous for automated tests to be able to run in process with the test harness code. For instance, I’d much rather do Alba testing of HTTP endpoints in .Net 5 where I’m able to quickly spin up an actual web service in memory and shut it down from my testing project. As opposed to the old, full .Net framework where you’d have to run the web service project in IIS or IISExpress first, then use HttpClient to address the service from your unit tests. The first, .Net 5/Alba approach is a much faster iteration and feedback cycle to support a Test Driven Development workflow than the 2nd approach.
Likewise, when given a choice between tests that can be run locally versus tests that can only be executed in a remote server location, give me the local tests every time. When and if you hit a scenario where you really need to run tests remotely *cough* serverless *cough*, that’s the one and only exception I can think of to my “never deploy from your local development box” rule. If depending on remote execution of tests, I’d at least want the ability to send my local development branch to the remote server at will. Just having a CI server build out pull request branches might get you there of course, but then you might be dependent upon being about to run that test suite in parallel with other CI builds. That’s not a show stopper, but it might make you have to invest more in your build automation to spin up isolated environments on demand.
Apollo Testing!
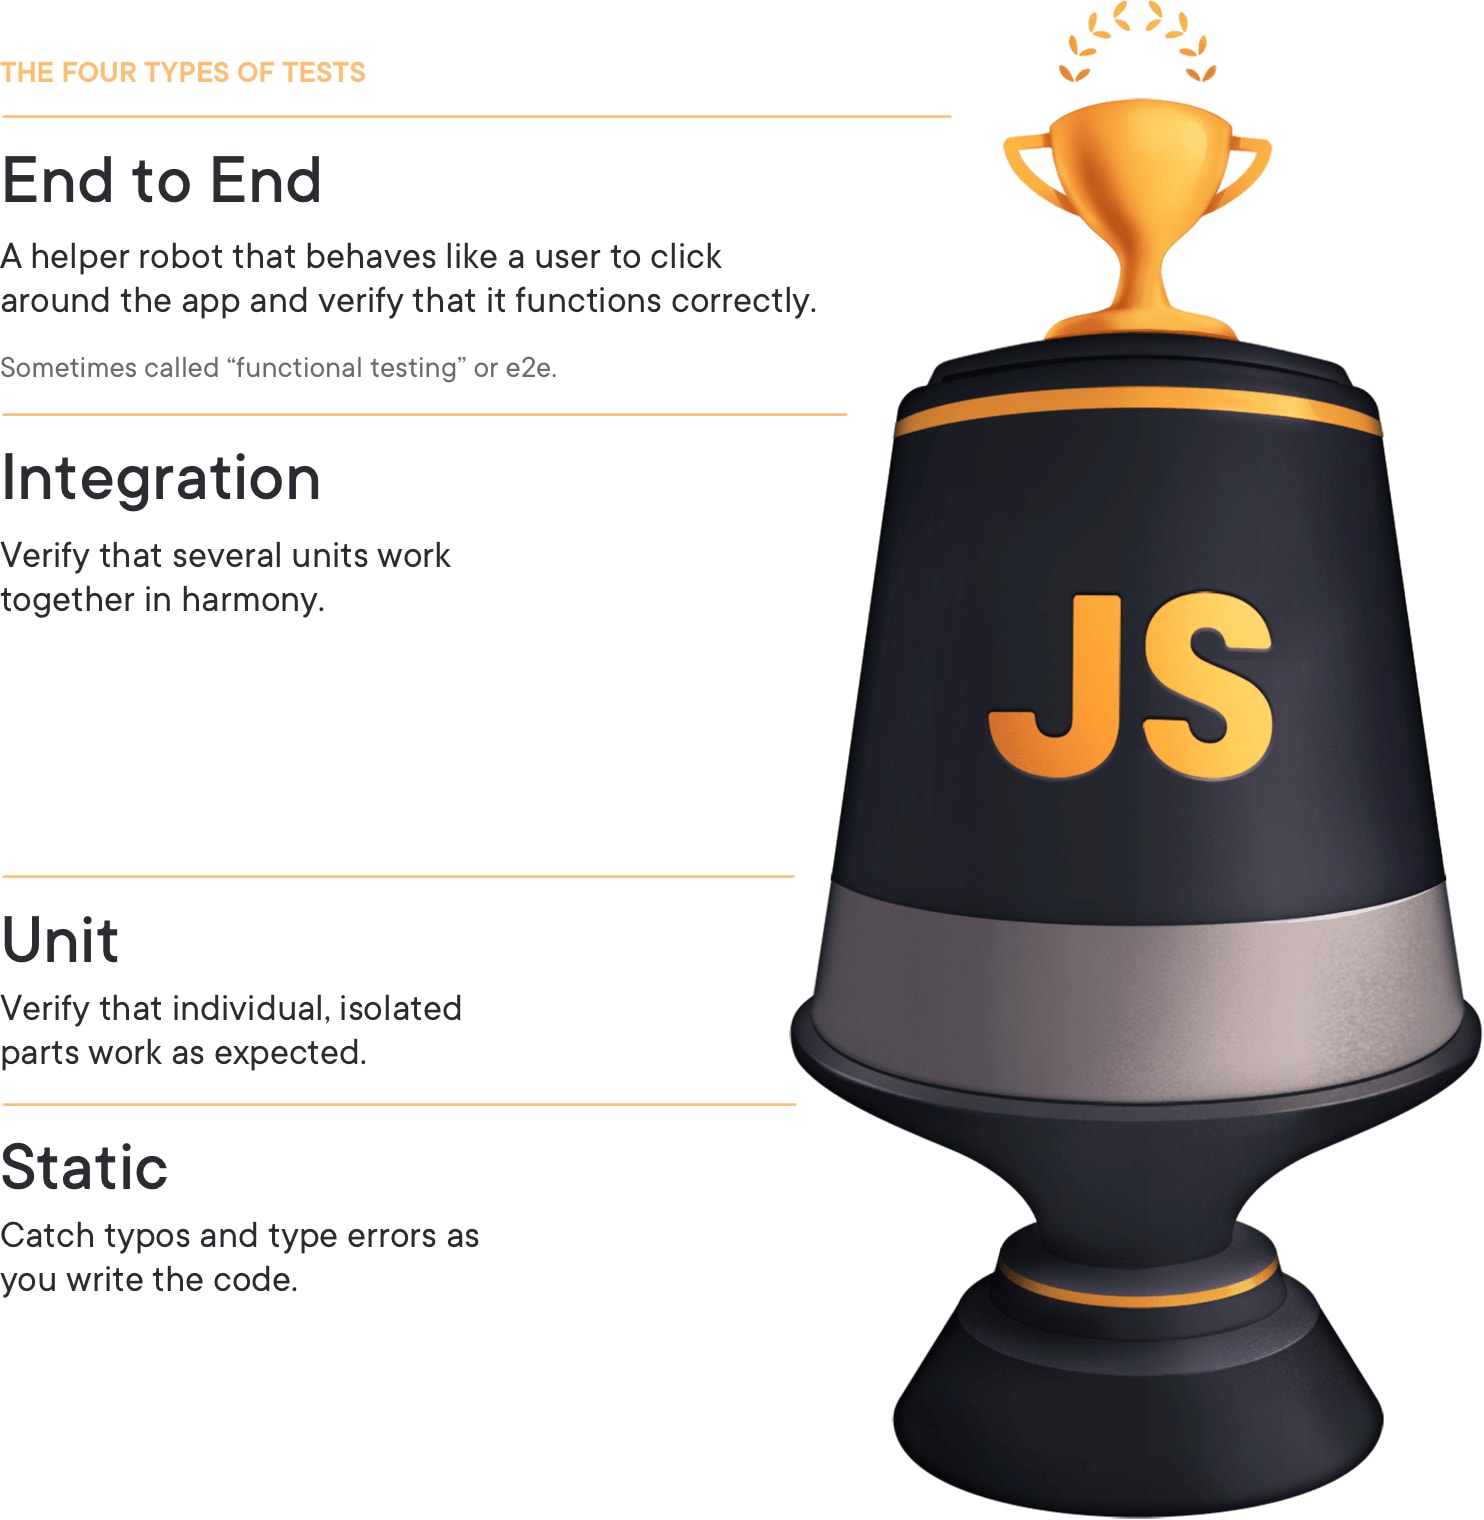
There’s plenty of debate over what the actual ration of UI tests to integration tests to unit tests should be, and plenty of folks have different metaphors than a “pyramid” to describe what they thing the ratio should be. I happen to like the integration test heavy ratio described in The Testing Trophy and Testing Classifications with the graphic below:
So from now on, I’m calling our intended testing approach the Apollo Testing Method!
What is the purpose of testing?
I’m just barely old enough that I started my official software development career in old fashioned waterfall models. In those days we did some unit testing with ad hoc testing tools to troubleshoot new code, but it wasn’t anywhere close to what developers do today with Test Driven Development and xUnit tools. As developers, we mostly ran the complete application on our development boxes and stepped through things manually to check out new code locally before throwing things over the wall to QA at the end of the project.
Regardless of whatever ad hoc, local testing developers did of their code locally, the only official testing that actually counted was the purely manual testing done by our testers in the testing environment that was supposed to exactly mimic the production environment (it never quite did, but that’s a story for another day). The QA team strictly used black-box testing with some direct access to the underlying database.
That old black-box testing approach at the end of the project was a much slower feedback cycle than we’re accustomed to today after the advent of Agile Software Development. The killer problem was that the testing feedback cycles were too slow to consider evolutionary design approaches because of the real fear of regression failures. It was also harder as a developer to address defects found in the testing cycle because you were frequently needing to work with code you hadn’t touched in many months that certainly wasn’t fresh in your mind. That frequently led to marathon debugging sessions while a helpful project manager came by your cubicle to cheerfully ask for any updates several times a day and crank up the pressure. As a developer you were also completely at the mercy of QA for information about what was really happening in the system when they found bugs.
In my mind, the most important element of Agile software development overall was the emphasis on improving feedback cycles. Faster feedback allowed
Testing is not about proving that our code works perfectly so much as a way to find and remove enough problems from the code that it can be deployed to production. I think this is an important approach because it allows us to use faster, finer grained testing approaches like isolated unit testing or intermediate level white-box integration tests that are generally faster running and cheaper to build than classic black-box, end to end tests.
What’s Next?
My organization has started an effort to introduce much more integration testing into our development processes as a way of improving quality and throughput. To help out on that, I’m going to attempt to write a series of blog posts going into specific areas about tools and techniques, but for right now I’m just jotting down this stream of consciousness brain dump to get started.
Based on what I think we need to establish at work, I’m thinking to cover:
.Net IHost bootstrapping and lifecycle within xUnit.Net or NUnit. I’m much more familiar with xUnit.Net from recent development, but we mostly use NUnit at work so I’ll be trying to cover that base as well.
HTTP API testing, which will inevitably feature Alba
Dealing with databases in tests, and that’s gonna have to cover both RDBMS databases and probably Mongo Db for now
Message handler testing with MassTransit and NServiceBus (we use both in different products)
Another brain dump on doing end to end testing after a meeting today about the CI of one of our big systems.
How should automated testing be integrated into the development cycle, and who should be responsible for these tests, and why is the obvious answer a very close collaboration between testers, developers, and even business experts
This will be a bigger stretch for me, but maybe get into how to do some semi-integration testing of an Angular front end with NgRX.
After talking through some of our issues with test automation at work, I think I’d like to blog about some of the positive things we did with Storyteller. I’ve been increasingly frustrated with xUnit.Net (and don’t think NUnit would be much better) for integration testing, so I’ve got quite a bit of notes about what an alternative tool optimized for integration tests could look like I wouldn’t mind publishing.
Alba is a small library to facilitate easier integration testing of web services built on the ASP.Net Core platform. It’s more or less a wrapper around the ASP.Net TestServer, but does a lot to make testing much easier than writing low level code against TestServer. You would use Alba from within xUnit.Net or NUnit testing projects.
I outlined a proposal for Alba V5 a couple weeks back, and today I was able to publish the new Nuget. The big changes are:
The old SystemUnderTest type was renamed AlbaHost to make the terminology more inline with ASP.Net Core
The Json serialization is done through the configured input and output formatters within your ASP.Net Core application — meaning that Alba works just fine regardless of whether your application uses Newtonsoft.Json or System.Text.Json for its Json serialization.